<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="/feed.xml" rel="self" type="application/atom+xml" /><link href="/" rel="alternate" type="text/html" /><updated>2026-06-04T00:37:37+00:00</updated><id>/feed.xml</id><title type="html">Painted Harmony Group - Data Science</title><subtitle>Exploring topics in Analytics, Operations Research, Mathematics, Probability and Statistics.</subtitle><author><name>Miles Porter</name></author><entry><title type="html">LLMs Are Random Variables, Not Functions</title><link href="/2026/06/02/llms-are-random-variables-not-functions.html" rel="alternate" type="text/html" title="LLMs Are Random Variables, Not Functions" /><published>2026-06-02T17:00:00+00:00</published><updated>2026-06-02T17:00:00+00:00</updated><id>/2026/06/02/llms-are-random-variables-not-functions</id><content type="html" xml:base="/2026/06/02/llms-are-random-variables-not-functions.html"><![CDATA[<h1 id="functions-random-variables-and-why-llms-are-not-deterministic-systems">Functions, Random Variables, and Why LLMs Are Not Deterministic Systems</h1>

<p>In the United States, by around 8th grade (ages 13–14), students are introduced to the concept of a <strong>function</strong>. This idea becomes foundational across nearly all of mathematics, including algebra, trigonometry, Euclidean geometry, calculus, differential equations, linear algebra, and abstract algebra.</p>

<p>A standard definition of a function is:</p>

<blockquote>
  <p>A function is a relation between two sets that assigns each element of the first set to exactly one element of the second set.</p>
</blockquote>

<p>More formally, if:</p>

\[f : A \rightarrow B\]

<p>then for every:</p>

\[x \in A\]

<p>there exists exactly one:</p>

\[y \in B\]

<p>such that:</p>

\[f(x) = y\]

<p>This <strong>“exactly one output per input”</strong> property is the key structural constraint that defines a function.</p>

<hr />

<h2 id="a-critical-asymmetry">A Critical Asymmetry</h2>

<p>It is important to emphasize a subtle but critical asymmetry:</p>

<ul>
  <li>Multiple inputs may map to the same output (<strong>many-to-one is allowed</strong>)</li>
  <li>A single input may not map to multiple outputs (<strong>one-to-many is not allowed</strong>)</li>
</ul>

<p>So it is perfectly valid that:</p>

\[f(x_1) = y\]

<p>and</p>

\[f(x_2) = y\]

<p>with</p>

\[x_1 \neq x_2\]

<p>However, the following is <strong>not</strong> valid for a function:</p>

\[f(x) = y_1\]

<p>and</p>

\[f(x) = y_2\]

<p>with</p>

\[y_1 \neq y_2\]

<p>This deterministic mapping structure is what makes functions so powerful. It forms the foundation for derivatives, integrals, transformations, and essentially all of continuous mathematics.</p>

<hr />

<h1 id="random-variables-and-probability">Random Variables and Probability</h1>

<p>In probability theory, we introduce a different kind of object: the <strong>random variable</strong>.</p>

<p>A random variable is often defined as a function:</p>

\[X : \Omega \rightarrow \mathbb{R}\]

<p>In this sense, a random variable is still technically a function.</p>

<p>The key difference is that we do not typically focus on the deterministic mapping itself. Instead, we associate the variable with a <strong>probability distribution</strong> that governs which outcomes are likely.</p>

<p>Rather than asking:</p>

\[X(\omega) = x\]

<p>we ask questions such as:</p>

\[P(X = x)\]

<p>or</p>

\[P(X \in S)\]

<p>for some set $S$.</p>

<p>In other words, probability theory shifts the focus from deterministic outputs to <strong>distributions over possible outputs</strong>.</p>

<p>Statistics then reverses the direction of inference: we observe samples and attempt to infer properties of the underlying distribution.</p>

<hr />

<h1 id="why-llms-behave-like-stochastic-systems">Why LLMs Behave Like Stochastic Systems</h1>

<p>This distinction becomes especially important when thinking about modern generative AI systems such as <strong>Large Language Models (LLMs)</strong>.</p>

<p>At a computational level, an LLM can be viewed as a function:</p>

\[f_{\theta}(p)
\rightarrow
\text{distribution over tokens}\]

<p>where:</p>

<ul>
  <li>$p$ is the prompt</li>
  <li>$\theta$ represents the learned model parameters</li>
</ul>

<p>However, the key point is that the model does <strong>not</strong> directly produce a single fixed output.</p>

<p>Instead, it produces a probability distribution, and the final response is typically obtained by sampling from that distribution:</p>

\[y \sim P_{\theta}(\cdot \mid p)\]

<p>This means that for the same input prompt $p$, multiple different outputs $y$ can be generated across different runs.</p>

<p>So while the underlying model parameters are deterministic, the output generation process is stochastic.</p>

<hr />

<h1 id="a-simple-experiment">A Simple Experiment</h1>

<p>Consider the prompt:</p>

<blockquote>
  <p>“Write a paragraph about how to pick your favorite color.”</p>
</blockquote>

<p>Running this prompt multiple times will produce different—but still valid—responses.</p>

<p>Each response is typically:</p>

<ul>
  <li>Coherent</li>
  <li>Relevant</li>
  <li>Grammatically correct</li>
</ul>

<p>Yet the responses will not necessarily be identical.</p>

<p>This variability is not noise in the traditional sense. It is a direct consequence of sampling from a learned probability distribution over language.</p>

<h1 id="a-more-complicated-experiment">A More Complicated Experiment</h1>

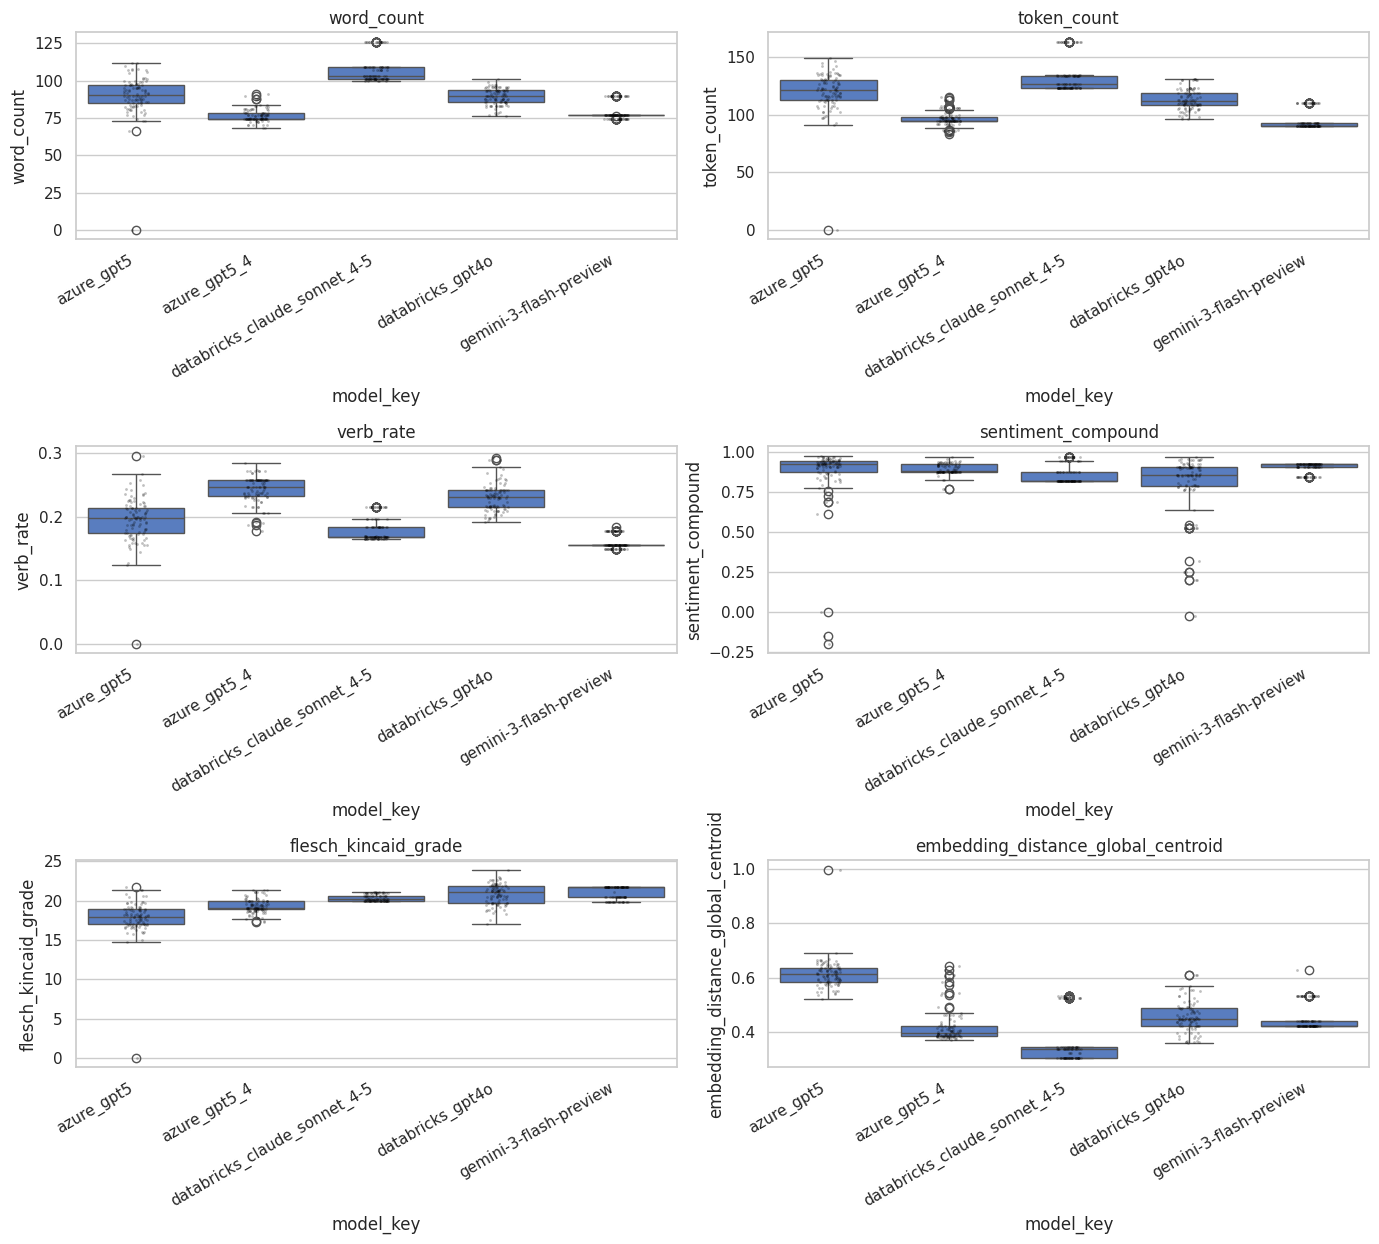
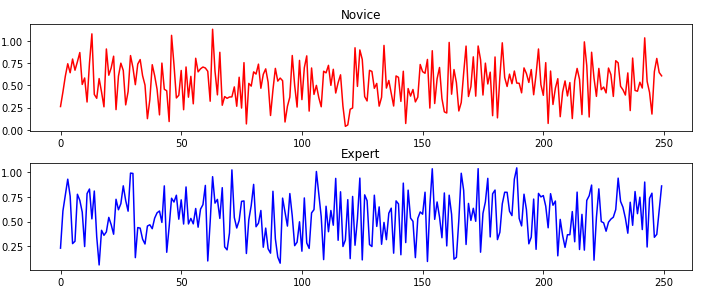
<p>The following plot shows how responses vary from LLM to LLM. This graph was generated by using the same prompt 100 times in each of the LLMs listed. The resulting language-related qualitative metrics were then calculated. Some models have a “temperature” parameter that can increase or decrease the amount of randomness or creativity in the LLM response. For this experiment, the temperature value was set to 0 for those models that have that parameter available. This encouraged the model to be as non-stochastic as possible when generating responses.</p>

<p><img src="/images/combined_plot.png" alt="combined plot" /></p>

<p>From the plot above, we can clearly see two things. First, across all of the LLMs, the response to the prompt was stochastic. Second, different models demonstrated different amounts of variance in the quantitative metrics of the text that was generated. (Note that this experiment was limited specifically to the English language.)</p>

<p>The prompt used for the experiment above was: “Write a concise paragraph explaining the significance of reproducibility in machine learning experiments.” The system prompt was: “You are a helpful assistant.”</p>

<hr />

<h1 id="the-value-and-risk-of-stochastic-generation">The Value and Risk of Stochastic Generation</h1>

<p>This stochasticity is central to both the power and the risk of LLMs.</p>

<h2 id="benefits">Benefits</h2>

<p>Stochastic generation enables:</p>

<ul>
  <li>Creative variation</li>
  <li>Idea generation</li>
  <li>Exploration of alternative phrasings</li>
  <li>Discovery of alternative solutions</li>
</ul>

<h2 id="risks">Risks</h2>

<p>At the same time, it introduces:</p>

<ul>
  <li>Non-zero probability of incorrect information</li>
  <li>Inconsistency across runs</li>
  <li>Difficulty in guaranteeing correctness without external verification</li>
</ul>

<p>Importantly, these risks do not disappear with increased scale or capability.</p>

<p>They are structural properties of the sampling process itself.</p>

<hr />

<h1 id="implications-for-deployment">Implications for Deployment</h1>

<p>In practice, this means LLMs should not be treated as deterministic, truth-preserving systems.</p>

<p>They are better understood as <strong>probabilistic generators</strong> that require:</p>

<ul>
  <li>Validation layers</li>
  <li>External grounding (retrieval systems, tools, databases, APIs)</li>
  <li>Testing across distributions of inputs</li>
  <li>Monitoring for failure modes over time</li>
</ul>

<p>This is similar in spirit to how humans are evaluated in safety-critical roles.</p>

<p>We do not assume correctness from a single response or test. Instead, we rely on:</p>

<ul>
  <li>Repeated evaluation</li>
  <li>Certification</li>
  <li>Ongoing oversight</li>
  <li>Performance monitoring</li>
</ul>

<hr />

<h1 id="closing-thought">Closing Thought</h1>

<p>LLMs are not simply <em>“right or wrong”</em> machines.</p>

<p>They are systems that generate outputs according to learned probability distributions.</p>

<p>That makes them powerful.</p>

<p>But it also means their outputs should be interpreted as:</p>

<blockquote>
  <p>Useful suggestions drawn from a distribution, not guaranteed facts.</p>
</blockquote>]]></content><author><name>Miles Porter</name></author><summary type="html"><![CDATA[Functions, Random Variables, and Why LLMs Are Not Deterministic Systems]]></summary></entry><entry><title type="html">Dendrites Aren’t Digital</title><link href="/2026/02/22/data_science_42.html" rel="alternate" type="text/html" title="Dendrites Aren’t Digital" /><published>2026-02-22T05:00:00+00:00</published><updated>2026-02-22T05:00:00+00:00</updated><id>/2026/02/22/data_science_42</id><content type="html" xml:base="/2026/02/22/data_science_42.html"><![CDATA[<h1 id="dendrites-arent-digital">Dendrites Aren’t Digital</h1>
<h3 id="how-artificial-and-biological-neural-networks-differ">How Artificial and Biological Neural Networks Differ</h3>
<p>Miles Porter<br />
Feb 22, 2026</p>

<hr />

<p>At a recent AI summit that I organized for my company, it became clear to me that not everyone fully understands the basics of generative AI, or artificial neural networks in general. As a result, now seems like a good time to pause and put down some of my thoughts on how artificial neural network systems differ from biological systems.</p>

<p>Some background: I studied applied mathematics at Colorado State University in the early 90s. One of the areas I focused on was pattern analysis and neural networks. Neural nets had been around for a while, actually going back to the 60s or before. What had changed in the 90s was that new advances in computing power were making it possible to run larger and larger neural networks. This was a time before cloud computing, and really even before the internet. Most of the networks that I worked on consisted of a few layers of fully connected nodes. However, their power seemed really amazing. One experiment we did was to train a neural network to learn the logistic map. I recreated that work using TensorFlow later here: https://github.com/fractalbass/simple_neural_net</p>

<p>Back in grad school, we didn’t have TensorFlow and Keras, so we had to write the network algorithms by hand. I spent hours writing for-loops in C and dealing with how to numerically implement the gradient descent algorithm — literally to the point of tears.</p>

<p>And, aside from some mild emotional scarring, I was left with a huge realization: mathematically modeled neural networks are VERY DIFFERENT from biological “wet” neural networks that I had studied in my basic biology classes in some pretty fundamental and very important ways.  One of those has to do with how signals flow through artificial vs biological networks.</p>

<hr />

<h2 id="synchronized-vs-non-synchronized-networks">Synchronized vs. Non-Synchronized Networks</h2>

<p>In a numerical neural network, nodes and synapses are modeled, but the flow through the network is governed by strict timing. Signals flow from layer to layer and node to node in a preset order, and that order is critical. When training a neural network, a signal is passed into the network and the output is observed at the other end. That output is compared to some expected training value, and the error is then “back-propagated” back through the neural network and used to adjust the parameters of each node in order to reduce the error just a little bit. Then a new pattern is passed in and the output observed. That output is compared to the expected training value and the error is, again, back-propagated through the neural network. This process continues over and over and over. There are some slight variations on this process — such as saving up all the updates and applying them all at once (batch mode), or tweaking the method of calculating the errors — but essentially the process remains the same. The point here is that it is a VERY STRUCTURED process. That is necessary because the algorithm for minimizing the error coming out of the network depends on the chain rule in calculus.</p>

\[\frac{d}{dx} f(g(x)) = \frac{df}{dg}\Big|_{g(x)} \cdot \frac{dg}{dx}\]

<p>That $f(g(x))$ part is really important. Let’s say that I have a 5-layer neural network, and I want to update the weights in the top layer based on some observed error. To do that, I would need to do the following:</p>

\[\frac{\partial L}{\partial w^{(5)}_{ij}}=\frac{\partial L}{\partial a^{(5)}_i}\cdot\frac{\partial a^{(5)}_i}{\partial z^{(5)}_i}\cdot\frac{\partial z^{(5)}_i}{\partial a^{(4)}_j}\cdot\frac{\partial a^{(4)}_j}{\partial z^{(4)}_j}\cdot\frac{\partial z^{(4)}_j}{\partial a^{(3)}_k}\cdot\frac{\partial a^{(3)}_k}{\partial z^{(3)}_k}\cdot\frac{\partial z^{(3)}_k}{\partial a^{(2)}_m}\cdot\frac{\partial a^{(2)}_m}{\partial z^{(2)}_m}\cdot\frac{\partial z^{(2)}_m}{\partial a^{(1)}_n}\cdot\frac{\partial a^{(1)}_n}{\partial z^{(1)}_n}\cdot\frac{\partial z^{(1)}_n}{\partial w^{(5)}_{ij}}\]

<p>Which is a friggin’ mess.</p>

<p>But the important thing is that in order to do this, I need to compute partial derivatives for the 5th layer, then the 4th, then the 3rd, and so on up to the first layer, in order to update the weights in each layer. This is the core concept behind “back”-propagation of errors. If the network didn’t have this preset structure, this becomes very, very difficult to do. The network needs to fire completely through one time, then everything stops and the error is computed before optimization can take place.</p>

<p>Biological neural networks differ from artificial neural networks in some other critical ways too:</p>

<ol>
  <li>Biological neural networks use both electrical and chemical signals.</li>
  <li>Biological neural networks have extremely complex topologies that are constantly changing.</li>
  <li>Biological neural networks don’t have strictly synchronized digital timing.</li>
  <li>Biological neural networks include neurons that fire at different speeds and delays.</li>
  <li>Biological neural networks are decentralized and involve local plasticity rules rather than centralized gradient-based optimization.</li>
  <li>Biological neural networks are analog systems, artificial neural networks are digital.</li>
</ol>

<p>All of these factors combine to make back-propagation of errors essentially impossible in biological neural networks.</p>

<hr />

<h3 id="looking-ahead">Looking Ahead</h3>

<p>Most artificial neural networks in practice follow what I described above in terms of their structure and algorithms. However, there are a few exceptions.  One of these exceptions can be found in a paper written in 1997, which proposed a “third generation” of artificial neural networks called “spiking neural networks”: <a href="https://igi-web.tugraz.at/people/maass/psfiles/85a.pdf">Maass (1997) — “Networks of Spiking Neurons: The Third Generation of Neural Networks”</a></p>

<p>Spiking neural networks differ from traditional artificial neural networks in a couple of critical ways:</p>

<ol>
  <li>The neurons in a spiking neural network store up input signals until they reach some critical threshold and then fire.</li>
  <li>The firing of a spiking neural network is binary (0 or 1). This kind of binary function is not differentiable, which means it cannot be optimized by gradient descent (the chain rule) or any other similar process.</li>
</ol>

<p>Because of point 2, optimizing (training) a spiking neural network becomes a non-convex optimization problem — in other words, they are very difficult to train. However, quantum computing might provide a potential solution. Quantum annealing is an approach specifically designed for optimization problems. However, we are a long way from having this approach enter the mainstream of computing.</p>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>What I hope readers take away from this post is that artificial neural networks — which are the foundation of the current “AI” buzz — differ in some really dramatic ways from biological neural networks.</p>

<p>Stay tuned for more articles on topics related to data science and AI.</p>

<hr />

<p><em>Notice: The content of this article was initially written by Miles Porter — a human. AI technology has been used to proofread and format the content. AI systems can hallucinate and make mistakes. It is important to verify and double-check the above content.</em></p>]]></content><author><name>Miles Porter</name></author><summary type="html"><![CDATA[Dendrites Aren’t Digital How Artificial and Biological Neural Networks Differ Miles Porter Feb 22, 2026]]></summary></entry><entry><title type="html">Responsible AI in an Irresponsible World</title><link href="/general/2025/10/21/data_science_41.html" rel="alternate" type="text/html" title="Responsible AI in an Irresponsible World" /><published>2025-10-21T05:20:00+00:00</published><updated>2025-10-21T05:20:00+00:00</updated><id>/general/2025/10/21/data_science_41</id><content type="html" xml:base="/general/2025/10/21/data_science_41.html"><![CDATA[<h1 id="yeah--it-has-been-a-while">Yeah.  It has been a while.</h1>

<h2 id="intro">Intro</h2>

<p>Responsible AI, as I have been thinking of it, is made up of 6 pillars:</p>

<ul>
  <li>Fairness / Bias</li>
  <li>Reliability / Safety</li>
  <li>Privacy / Security</li>
  <li>Inclusiveness</li>
  <li>Transparency</li>
  <li>Accountability</li>
</ul>

<p>Originally, I was going make this about all of the above, but let’s focus in something a bit more specific: Accountability. Typically, when I think of Accountability in RAI, I tend to think of “Making people accountable for AI”.  And, that is definitely part of that pillar.  I seem to be reading more and more about sustainability and how it is also part of accountability.  Now, a TON of discussion and papers have been written about the sustainability aspects of training large language models.  This series from MIT is particularly informative:</p>

<p>But, I believe that sustainability concerns (and frankly business concerns) don’t end there.  I would like to explore two specific examples of how sustainability can play a role in GenAI at inference time.</p>

<h2 id="simple-example-1--regression">Simple Example 1.  Regression</h2>

<p>I recently wrote a Jupyter notebook that did a comparison between using the deterministic approach to linear regression vs using an LLM.  Now, you may be thinking something along the lines of “That is just crazy!”  …and you’d be correct.  I was curious, however, just how “crazy it was.”  My experiment involved creating 1000 points that were normally distributed around a line.  I wanted to see just how much difference there would be in computation time between using a Scipy based algorithm vs using an LLM (OpenAI O3).  For this experiment, I went with GPT5.  One of the first problems that I ran into was dealing with getting all 1000 points stuffed into the LLM input tokens, so just to make things more simple, I decided to narrow down the problem to using 10 points.  My prompt was, basically, “Please use linear regression to determine the best fit line through the following set of points [(-3.00, -2.412), …]”.  The results were so lopsided that I then decided to handicap the Scipy approach and force it to use all 1000 points.  The following graph shows the different between the Scipy model and the LLM for accuracy and computation time.</p>

<p>So, the LLM approach was actually 58950 slower than the Scipy approach!  I knew that it would be bad, but I didn’t anticipate just HOW bad.  (I should note here that some of the LLM compute time was clearly spent sending the data back and forth to Azure OpenAI Foundry.  However, since there is no real option to run O3 on a local machine, that is no way around it.</p>

<p>But, let’s consider a second example… doing sentiment analysis on a dataset and see what we come up with…</p>

<h2 id="simple-example-2--sentiment">Simple Example 2.  Sentiment</h2>

<h2 id="bottom-line--do-you-have-to">Bottom line.  Do you have to?</h2>

<h2 id="what-next">What next?</h2>

<p>Attend my presentation at the Trimble Dimensions Conference in Las Vegas at the Venetian on Nov. 10th.</p>

<h1 id="conclusion">Conclusion</h1>

<p>Thanks, and see ya’ in Vegas?</p>

<p>- Miles</p>

<p>;)</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Yeah. It has been a while.]]></summary></entry><entry><title type="html">Mama Said There’d be Days Like This</title><link href="/general/2024/01/24/data_science_40.html" rel="alternate" type="text/html" title="Mama Said There’d be Days Like This" /><published>2024-01-24T08:09:00+00:00</published><updated>2024-01-24T08:09:00+00:00</updated><id>/general/2024/01/24/data_science_40</id><content type="html" xml:base="/general/2024/01/24/data_science_40.html"><![CDATA[<h1 id="experimentation-means-failure">Experimentation Means Failure?</h1>

<p>In the movie The Princess Bride there is a scene with Inigo and Dread Pirate Roberts having a sword fight on the Cliffs of Insanity. Inigo presses Roberts to remove his mask and reveal his identity.  When Inigo says, “I must know,” Westley replies, “Get used to disappointment.”</p>

<p>This is a great metaphor for working in data science.  If you really are doing data science, then you need to “Get used to disappointment.”</p>

<h1 id="roc-and-auc">ROC and AUC</h1>

<p>These three letter acronyms are important, particularly in the context of building classification models.  ROC or Receiver Operating Characteristic is a graph that shows the impact of threshold values on a binary classifier.  Area Under Curve, also often referred to as “lift”, corresponds to the improvement that a model has over using a naive guess for the classification.  Any value of AUC that is below .5 shows that your model is actually WORSE that a random guess.</p>

<p>Yes.  It happens.</p>

<p><img src="/images/bad_auc.png" alt="Bad AUC" /></p>

<p>This is an actual AUC from a project that I am working on.</p>

<p>Yes.  I trained a binary classifier that is actually “dumber than dumb.”</p>

<h1 id="the-point">The Point</h1>

<p>Thomas Edison <a href="https://www.smithsonianmag.com/innovation/7-epic-fails-brought-to-you-by-the-genius-mind-of-thomas-edison-180947786/">once said</a></p>

<blockquote>
  <p>“I have not failed 10,000 times—I’ve successfully found 10,000 ways that will not work.”</p>
</blockquote>

<p>“Finding ways that will not work” is part of experimentation.  It is a critical part of all science, it is how we find insights, and how we learn.</p>

<p>That is all for this extremely short blog post.  Carry on and keep finding ways that will not work!</p>

<ul>
  <li>Miles</li>
</ul>

<p>;)</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Experimentation Means Failure?]]></summary></entry><entry><title type="html">Collaborating Filtering for Mere Mortals Part 2: A Neural Network Approach</title><link href="/general/2024/01/08/data_science_39.html" rel="alternate" type="text/html" title="Collaborating Filtering for Mere Mortals Part 2: A Neural Network Approach" /><published>2024-01-08T08:09:00+00:00</published><updated>2024-01-08T08:09:00+00:00</updated><id>/general/2024/01/08/data_science_39</id><content type="html" xml:base="/general/2024/01/08/data_science_39.html"><![CDATA[<h1 id="introduction">Introduction</h1>

<p>In my previous post, I wrote about how matrix based collaborative filtering works and went through a simple example implementation using the Surprise package in python.  Continuing on with that topic, I wanted to explore an alternative approach to this problem that uses neural networks.</p>

<p>Recall that our previous approach was essentially about creating a matrix that maps users and items.  This matrix is made up of previously known ratings from users.  In our example, the items were movies and the ratings were scores from 0.5 to 5.0.  Since not all users have watched all movies, the matrix in question is very sparse.  The goal, then, is to attempt to find a solution that fills in the gaps.</p>

<p>Using matrix factorization and singular value decomposition is just one approach to solving this problem.  Another approach involves using neural networks, or more accurately multi-layer perceptrons or “MLPs”.</p>

<h1 id="the-movielens-dataset">The MovieLens Dataset</h1>

<p>To demonstrate how this works, I am again using the MovieLens 100k dataset that consists of users, movies and rankings.  More information about the MovieLens dataset <a href="https://grouplens.org/datasets/movielens/">can be found on the GroupLens website.</a></p>

<h1 id="network-structure">Network Structure</h1>

<p>Neural networks similar to the one in this example are frequently referred to as “deep learning”, but IMO it really is not.  As we will see below, the network in use here has only a few layers.  Deep learning networks typically have dozens or more layers and lots of parameters.  For example, Yolo V8 has 53 convolutional layers alone, and GPT3.5 has 96 layers and 175B trainable parameters.  These types of networks are DEEP!  As we will see, the neural network in this example is very basic and very shallow.</p>

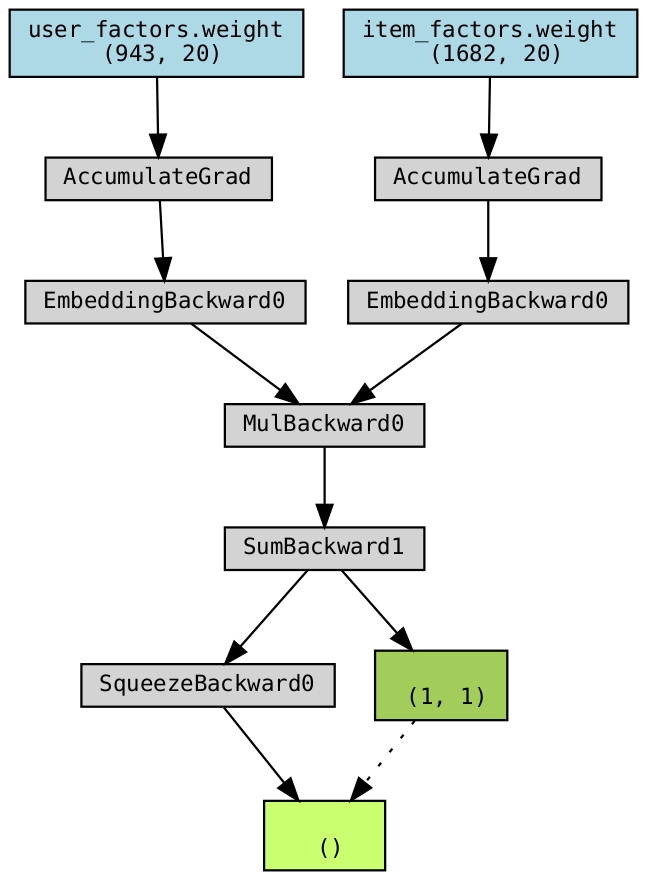
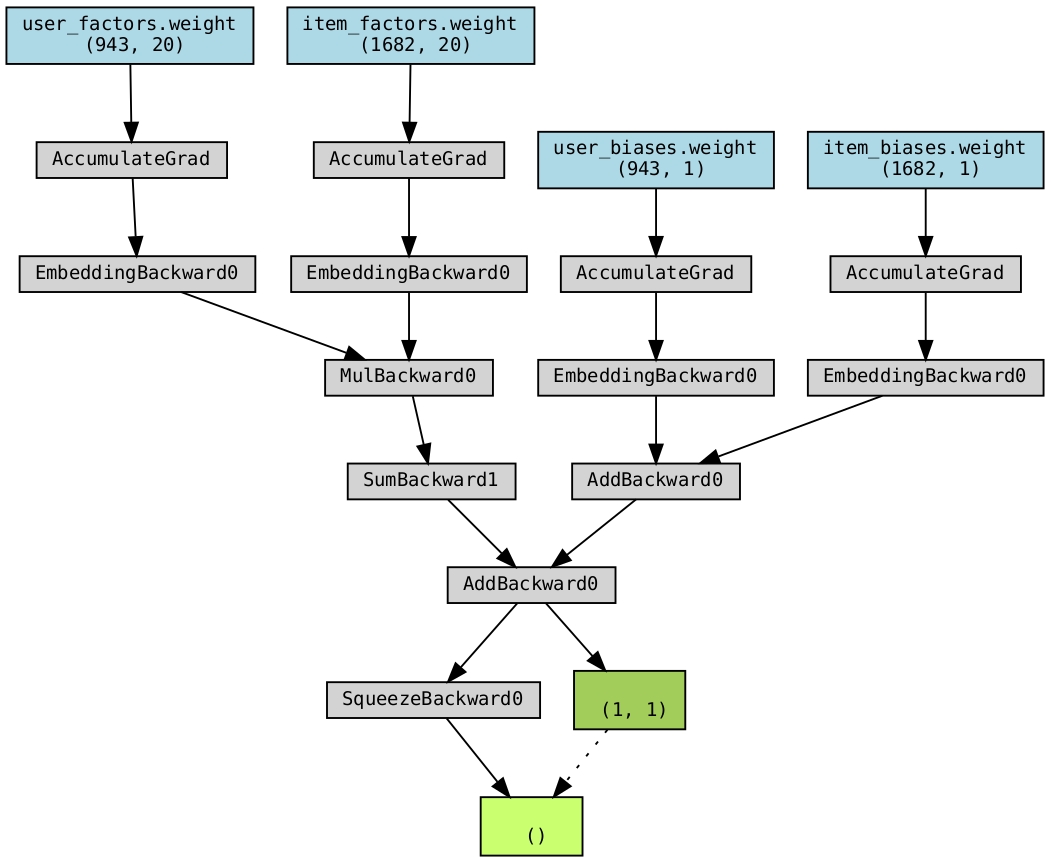
<p>To understand how the network is structured, let’s start with a simple diagram.  The following diagram was created from the torchviz packaged.  We can see that the network starts with two main sets of inputs, user_factors and item_factors.</p>

<p><img src="/images/dlrm_simple_network.jpg" alt="Simple Network Architecture" /></p>

<p>The key thing to understand here is that an initial “embedding” is taking place in order to feed information into the network.  This is done by creating a mapping from a given user and an embedding vector of some length.  In the case of my code for the movie example, the embedding vectors have a length of 20.  Initially, the values of the embedding vectors are randomized.  As the network continues to train, back propagation is used to update these values.  As training progresses, the embedding vectors start to “understand the latent structure” hidden in the data.</p>

<p>As with the previous example with collaborative filtering, the neural network approach also suffers from the “cold-start problem.”  The cold-start problem refers to the difficult of providing accurate recommendations for new or “cold” users that have limited historical data.  (Yes, I did lift that from ChatGPT.)  Simply put, in order for us to do inference, we are going to have to have trained our model on at least some information for a given user and item.</p>

<h1 id="introducing-factor-biases">Introducing Factor Biases</h1>

<p>One of the challenges in building models like this is that users and items can suffer from biases.  For example, one user might be particularly generous in their rankings compared to others.  Or, certain items may have been reviewed more times than others.  In the paper “Factorization Meets the Neighborhood: a Multifaceted Collaborative Filtering Model.” (Proceedings of the 14th ACM SIGKDD international conference on Knowledge discovery and data mining (KDD ‘08), pp. 426-434. DOI: 10.1145/1401890.1401944), author Yehuda Koren presents a way to deal with this situation by introducing a vector for user and item biases.  The addition of these bias vectors can be seen in the next diagram.</p>

<p><img src="/images/dlrm_simple_network_with_biases.jpg" alt="Simple Network Architecture" /></p>

<p>Note that the bias vectors are of length 1.  They are basically a trained value that boosts or discounts the overall value of the prediction for a given user and item.  Like the embedding vectors, these values are updated as the network gets trained.</p>

<h1 id="some-code">Some Code</h1>

<p>The following includes some code that will train a neural network to make ratings predictions based on the MovieLens 100k dataset.  In this code, I have configured the system to run 450 training epochs.  With my Quadro GP100 (which is a slightly older GPU), this process took about an hour.</p>

<pre>
import os
import pandas as pd
import torch
import torch.nn as nn
import torch.optim as optim
from torch.utils.data import Dataset, DataLoader, random_split
from torchviz import make_dot
import logging

# Set up logging
logging.basicConfig(level=logging.DEBUG)

# Set the device (CPU/GPU)
device = torch.device("cpu")
if torch.cuda.is_available():
    device = torch.device("cuda")
    print(f"PyTorch is using GPU: {torch.cuda.get_device_name(0)}")
else:
    print("PyTorch is using CPU")

# Define a custom dataset class for MovieLens data
class MovieLensDataset(Dataset):
    def __init__(self, data_path):
        # Load data from a CSV file into a Pandas DataFrame
        self.data = pd.read_csv(os.path.join(data_path, "u.data"), sep="\t", header=None, names=["user_id", "item_id", "rating", "timestamp"])

    def __len__(self):
        return len(self.data)

    def __getitem__(self, idx):
        return self.data.iloc[idx]

# Define a recommender system model using PyTorch nn.Module
class RecommenderSystem(nn.Module):
    def __init__(self, n_users, n_items, n_factors=20):
        super().__init__()
        # Embedding layers for user and item factors
        self.user_factors = nn.Embedding(n_users, n_factors)
        self.item_factors = nn.Embedding(n_items, n_factors)
        # Embedding layers for user and item biases
        self.user_biases = nn.Embedding(n_users, 1)
        self.item_biases = nn.Embedding(n_items, 1)

    def forward(self, user, item):
        # Perform forward pass through the model
        user_factors = self.user_factors(user)
        item_factors = self.item_factors(item)
        user_biases = self.user_biases(user)
        item_biases = self.item_biases(item)
        
        rating = (user_factors * item_factors).sum(dim=1, keepdim=True)
        rating += user_biases + item_biases
        return rating.squeeze()
    
    def visualize_network(self, user, item):
        rating = self.forward(user, item)
        dot = make_dot(rating, params=dict(self.named_parameters()))
        return dot

# Method for training the model for one epoch
def train_epoch(model, train_loader, criterion, optimizer, device):
    model.train()
    for i in range(1, len(train_loader) + 1):
        row = train_loader.dataset.dataset.data.iloc[i - 1]
        try:
            user = torch.LongTensor([row["user_id"]])
            item = torch.LongTensor([row["item_id"]])
            rating = torch.FloatTensor([row["rating"]])
            
            user, item, rating = user.to(device), item.to(device), rating.to(device)

            optimizer.zero_grad()
            pred = model(user, item)
            loss = criterion(pred, rating.squeeze().float())
            loss.backward()
            optimizer.step()
        except Exception as e:
            print("Something blew up in training on row #{}!".format(i))
            print("Row: {}".format(row))
            exit(1)

# Method for evaluating the model
def evaluate(model, test_loader, device):
    model.eval()
    total_loss = 0
    total_count = 0

    with torch.no_grad():
        for i in range(1, len(test_loader) + 1):
            try:
                row = test_loader.dataset.dataset.data.iloc[i - 1]
                user = torch.LongTensor([row["user_id"]])
                item = torch.LongTensor([row["item_id"]])
                rating = torch.FloatTensor([row["rating"]])
                
                user, item, rating = user.to(device), item.to(device), rating.to(device)
                pred = model(user, item)
                total_loss += ((pred - rating) ** 2).sum().item()
                total_count += 1 #pred.size(0)
            except Exception as e:
                print("Something blew up in testing on row #{}!".format(i))
                print("Row: {}".format(row))
                exit(1)
    
    return total_loss / total_count

# Method to display predictions
def display_predictions(model, test_loader, item_names, device):
    model.eval()
    with torch.no_grad():
        for i in range(1, 10):
            row = test_loader.dataset.dataset.data.iloc[i - 1]
            user = torch.LongTensor([row["user_id"]])
            item = torch.LongTensor([row["item_id"]])
            rating = torch.FloatTensor([row["rating"]])

            user, item, rating = user.to(device), item.to(device), rating.to(device)
            pred = model(user, item)
            item_name = item_names.loc[item_names['item_id'] == row["item_id"], 'title'].values[0]
            print(f"Item Name: {item_name}, Actual Value: {rating.item()}, Predicted Value: {pred.item()}")

def get_item(loader, n):
    row = loader.dataset.dataset.data.iloc[n]
    user = torch.LongTensor([row["user_id"]])
    item = torch.LongTensor([row["item_id"]])
    rating = torch.FloatTensor([row["rating"]])
    return user.to(device), item.to(device), rating.to(device)

# Main function
def main():

    data_path = "./data/ml-100k"
    # Initialize MovieLens dataset and item names
    dataset = MovieLensDataset(data_path)
    item_names = pd.read_csv(os.path.join(data_path, "u.item"), sep="|", encoding="latin-1", header=None, names=["item_id", "title"], usecols=[0, 1])

    # Get the number of unique users and items
    n_users = dataset.data["user_id"].nunique()
    n_items = dataset.data["item_id"].nunique()

    # Split dataset into training and test sets
    train_size = int(0.9 * len(dataset))
    test_size = len(dataset) - train_size
    train_dataset, test_dataset = random_split(dataset, [train_size, test_size])

    # Create data loaders for training and testing
    train_loader = DataLoader(train_dataset, batch_size=32, shuffle=True)
    test_loader = DataLoader(test_dataset, batch_size=1, shuffle=False)


    # Initialize the recommender system model, criterion, and optimizer
    model = RecommenderSystem(n_users, n_items).to(device)
    criterion = nn.MSELoss()
    optimizer = optim.Adam(model.parameters(), lr=0.001)

    # # Visualize the network
    user, item, rating = get_item(train_loader, 0)
    dot = model.visualize_network(user, item)
    dot.render("network.gv", view=True)

    # Train the model for multiple epochs
    num_epochs = 10
    for epoch in range(1, num_epochs + 1):
        train_epoch(model, train_loader, criterion, optimizer, device)
        mse_train = evaluate(model, train_loader, device)
        mse_test = evaluate(model, test_loader, device)
        print(f"Epoch: {epoch}, Train MSE: {mse_train:.4f}, Test MSE: {mse_test:.4f}")

    # Display predictions for a subset of test data
    display_predictions(model, test_loader, item_names, device)

# Entry point
if __name__ == "__main__":
    main()

</pre>

<h1 id="results">Results</h1>

<p>The above code, which I ran on my desktop machine generated the following output:</p>

<p>(I have shorted the output here to make it a bit easier to consume.)</p>

<pre>
PyTorch is using GPU: Quadro GP100
Epoch: 1, Train MSE: 29.7299, Test MSE: 33.6222
Epoch: 2, Train MSE: 22.9194, Test MSE: 30.3332
Epoch: 3, Train MSE: 17.4325, Test MSE: 27.6297
...
Epoch: 450, Train MSE: 0.0414, Test MSE: 7.3477

Item Name: Kolya (1996), Actual Value: 3.0, Predicted Value: 2.773867130279541
Item Name: L.A. Confidential (1997), Actual Value: 3.0, Predicted Value: 3.0126101970672607
Item Name: Heavyweights (1994), Actual Value: 1.0, Predicted Value: 1.3654597997665405
Item Name: Legends of the Fall (1994), Actual Value: 2.0, Predicted Value: 1.8913805484771729
Item Name: Jackie Brown (1997), Actual Value: 1.0, Predicted Value: 0.6543256044387817
Item Name: Dr. Strangelove or: How I Learned to Stop Worrying and Love the Bomb (1963), Actual Value: 4.0, Predicted Value: 3.741678237915039
Item Name: Hunt for Red October, The (1990), Actual Value: 2.0, Predicted Value: 1.5932667255401611
Item Name: Jungle Book, The (1994), Actual Value: 5.0, Predicted Value: 5.35903263092041
Item Name: Grease (1978), Actual Value: 3.0, Predicted Value: 3.002894163131714
</pre>

<p>Here we can see that the network did a pretty good job of nailing the MovieLens 100K dataset.  It should be noted that to train the model on the data took around an hour for 450 epochs.  The collaborative filtering approach that I used in the previous post was significantly faster.</p>

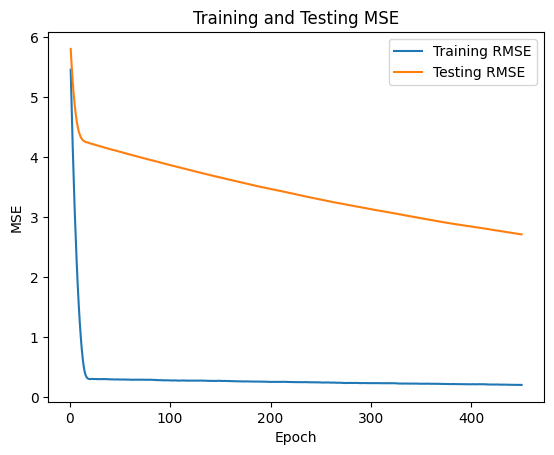
<p>The following graph shows the training curve for the network.  In the interest of time, I cut the training off at 450 epochs.  The performance of the holdout test set was still improving at that point.</p>

<p><img src="/images/dlmr_training_plot.png" alt="Network Learning Curve" /></p>

<h1 id="discussion">Discussion</h1>

<p>The MovieLens dataset contains 943 users and 1682 items.  Clearly, this is a pretty small dataset.  There have been a number of different approaches to dealing with this problem including the release of the <a href="https://github.com/pytorch/torchrec">Torchrec</a> domain library for Pytorch.  Torchrec provides a way to handle embeddings such that they can be better parallelized across multiple machines.  This allows network training to be scaled up to account for larger and larger datasets.  In 2019, Meta (the parent company of Facebook) released an open source solution for dealing with the problem.  Information about that approach can be found <a href="https://ai.meta.com/blog/dlrm-an-advanced-open-source-deep-learning-recommendation-model/">here</a>.</p>

<h1 id="conclusion">Conclusion</h1>

<p>In this post, I have discussed implementing a neural network based recommender system.  I discussed, at a high level, how the neural network approach in this post differs from the singular value decomposition approach that I covered in my previous post.  I included some examples of the network architecture both in it’s basic form, and with an added “bias” feature vector.  I included code written in Python that uses the pytorch framework and that can leverage a GPU.  I shared some initial results of the code showing how the network performed on a random hold-out test set.  Finally, I included a short discussion on directions for neural network based recommender systems.</p>

<p>I hope you have enjoyed this post!  Until next time…</p>

<p>Miles</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Introduction]]></summary></entry><entry><title type="html">Collaborative Filtering for Mere Mortals!</title><link href="/general/2024/01/05/data_science_38.html" rel="alternate" type="text/html" title="Collaborative Filtering for Mere Mortals!" /><published>2024-01-05T08:09:00+00:00</published><updated>2024-01-05T08:09:00+00:00</updated><id>/general/2024/01/05/data_science_38</id><content type="html" xml:base="/general/2024/01/05/data_science_38.html"><![CDATA[<h1 id="a-mere-mortals-guide-to-collaborative-filtering">A mere mortals guide to collaborative filtering.</h1>

<p>I recently went thru an advanced course on Google on collaborative filtering.  It was good, but DANG.  It was a little mathematically intense.  I thought I would go thru a similar exercise here to show how collaborative filtering can be used to make recommendations… and give a very basic code example.  For my example, I will use a MovieLens dataset similar to the one in the Google example.  I will use some comments from the approach outlined in “Data Mining for Business Analytics” by Shmueli, Bruce, Yahav, Patel, and Lichtendahl (ISBN 978-1-118-87936-8).  The approach specified in that text has examples in R, which are great… if you like R.  For those that don’t, I will conclude this post with an example that uses the open-source Surprise package (Simple Python Recommendation System Engine).</p>

<h2 id="first-some-background">First, some background:</h2>

<p>As outlined in the Google course, recommendation systems often typically have a three phase approach.  These phases include candidate generating, scoring and re-ranking.  In the candidate generation phase, two approaches; content-based filtering and collaborative filtering are used.  The goal of the candidate phase is to reduce the number of possible matches down to some reasonable number so that they can be scored.</p>

<blockquote>
  <p>For the sake of this discussion, we will use the terms “users” and “items” to represent the things that we are recommending to, and the things that we are recommending respectively.</p>
</blockquote>

<p>Content-based filtering focuses on similarities between items.  The example used in the Google tutorial is “If user A watches two cute cat videos, then the system can recommend cute animal videos to that user.”  This approach has one big advantage in that the model doesn’t need to worry about other users.  However, the model also requires that all the “items” have been tagged, and the quality of the results depends heavily on that tagging.</p>

<p>Collaborative-based filtering, on the other hand doesn’t require prior tagging.  In this approach similarities between users drives the recommendations.  One of the big challenges of collaborative based filtering include the fact that the model cannot include new items.  This is referred to as the cold-start problem.  There are a few techniques that can help address this and other issues including WALS.  I am going to defer discussion on that approach for another blog post.  Ultimately, Collaborative based filtering has one huge advantage over content based filtering, and that is that it can make recommendations that seem “serendipitous.”  For example, a user might enjoy watching cat videos and the system recommends other videos on knitting.  That association was “discovered” because other users that liked cat videos also liked knitting videos.  (It could happen.  Just sayin’.)</p>

<h2 id="the-basics-of-collaborative-filtering">The Basics of Collaborative Filtering:</h2>

<p>There are two flavors of collaborative filtering, user-based and item-based.  In User based collaborative the algorithm follows these steps:</p>

<h2 id="user-based-collaborative-filtering">User-based collaborative filtering:</h2>

<ol>
  <li>Identify those users that are most like the user of interest.</li>
  <li>Consider only those items that the user of interest has NOT purchased or ranked yet.</li>
  <li>Use the similar users items to recommend possible items to the user of interest.</li>
</ol>

<h2 id="item-based-collaborative-filtering">Item-based collaborative filtering:</h2>

<p>The user-based approach is straight forward, but suffers from a big problem if the number of users is very large.  Namely, the first step can be very costly in terms of compute.  A less expensive approach is to do the filtering based on the items instead.  That approach has the following steps:</p>

<ol>
  <li>Identify the ITEMS that were co-rated or co-purchased by any user with the item of interest.</li>
  <li>Recommend the most popular item or correlated item(s) among the similar items.</li>
  <li>For any given user, look at their items… and let those items recommend other items.</li>
</ol>

<p>For the purpose of this exploration we will continue with the item-based collaborative filtering approach.</p>

<h2 id="a-little-math">A Little Math:</h2>

<p>In order to determine the items in step 1, we need to come up with some metric to measure how similar items are.  The metric often used for this is referred to as the Pearson correlation metric.  Euclidean can also be used, but “does not perform well for collaborative filtering as some other measures” (Shmueli, et al.  Pg 345.)  This is explained in some detail in the Google tutorial mentioned at the beginning of this post, and I won’t elaborate on it further here in the interest of time.  (Not that you haven’t fallen asleep already unless you are a super data analytics nerd like me.  :) )</p>

<p>The Pearson Correlation metric can be expressed as…</p>

\[Corr(I_1, I_2) = \frac {\sum(r_{1,i} - \bar r_1)(r_{2,i} -\bar r_2)} {\sqrt{\sum(r_{1,i} - \bar r_1)^2} \sqrt{\sum(r_{2,i} - \bar r_2)^2}}\]

<p>(‘cause it ain’t a good blog post without out some painful LaTeX, right?)</p>

<p>That is great, but what does it mean?  It is important to understand that what we are really building behind the scenes is a matrix that associates users with items.  Our matrix, initially, is a very sparse because not every user has ranked every item.  The goal of the recommendation system, then, is to attempt to fill in the blanks in the matrix.  In order to do that, we can use a singular value decomposition approach (SVD) that generates three matricies, U, S, and V.  The U matrix represents the users, the V matrix represents the items, and the S matrix is diagonal matrix that is comprised of singular value such that the product of U,S and V approximates the original ratings matrix… with the gaps filled in.</p>

<p>Doing this requires a good deal of code that can potentially be very non-performant.  But, fear not… there are packages that make this entire process easy, performant and less error prone.  One such package for Python is the Surprise package.</p>

<h2 id="doing-this-with-code-the-easy-way">Doing This With Code (the easy way):</h2>

<p>Fortunately, a number of packages make this process much easier than having to do it by hand.  The Surprise python package is a popular package for doing recommendation.  The following example shows how it can be used.  This example loads data from the ml-100k dataset, which can be found here: (https://grouplens.org/datasets/movielens/100k/0)</p>

<p>The following code loads the movie recommendations, uses the Singular Value Decomposition (SVD) algorithm to solve the recommendation matrix (this is also discussed in the Google tutorial), and displays the results of the predictions of the first 10 records in the test set.  (Note that there is a test/train split involved in the code.)</p>

<p>The data in the training set has values of 0.5 - 5.0  This indicates the “score” that the given user gave the given item.  In some recommendation systems, this score could be binary.</p>

<p>The results are pretty accurate, typically within 1 of the actual ranking provided by the user in the training set.</p>

<pre>

import os
import pandas as pd
from surprise import Dataset
from surprise import Reader
from surprise import SVD
from surprise.model_selection import cross_validate
from surprise.model_selection import train_test_split

class Recommender:

    def movie_rating_prediction(self):
        # Load the data
        reader = Reader(line_format='user item rating timestamp', sep='\t')
        movie_data = Dataset.load_from_file('data/ml-100k/u.data', reader=reader)

        # Perform cross-validation
        algo = SVD()
        cross_validate(algo, movie_data, measures=['RMSE', 'MAE'], cv=5, verbose=True)

        # Train and test the algorithm
        trainset = movie_data.build_full_trainset()
        algo.fit(trainset)
        testset = trainset.build_testset()
        predictions = algo.test(testset)

        # Load movie titles
        movies = pd.read_csv('./data/ml-100k/u.item', sep='|', encoding='latin-1', header=None, usecols=[0, 1], names=['item', 'title'])

        # Display the item name, predicted rating, and actual rating for the first 10 rows in the test set
        print("\nItem Name, Predicted Rating, Actual Rating")
        for idx, pred in enumerate(predictions[:10]):
            movie_title = movies[movies['item'] == int(pred.iid)]['title'].values[0]
            print(f"{movie_title}, {pred.est:.2f}, {pred.r_ui:.2f}")


if __name__ == '__main__':
    recommender = Recommender()
    recommender.movie_rating_prediction()

</pre>

<p>Running this code produces the following results:</p>

<pre>
Evaluating RMSE, MAE of algorithm SVD on 5 split(s).

                  Fold 1  Fold 2  Fold 3  Fold 4  Fold 5  Mean    Std     
RMSE (testset)    0.9432  0.9384  0.9431  0.9277  0.9324  0.9370  0.0061  
MAE (testset)     0.7432  0.7379  0.7443  0.7331  0.7341  0.7385  0.0046  
Fit time          1.02    1.04    1.02    1.01    1.19    1.06    0.07    
Test time         0.15    0.14    0.14    0.14    0.20    0.15    0.02    

Item Name, Predicted Rating, Actual Rating
Kolya (1996), 3.91, 3.00
Mrs. Doubtfire (1993), 3.48, 4.00
Muriel's Wedding (1994), 3.50, 4.00
Shall We Dance? (1996), 4.17, 3.00
Stand by Me (1986), 4.14, 5.00
Ace Ventura: Pet Detective (1994), 3.66, 5.00
Mrs. Brown (Her Majesty, Mrs. Brown) (1997), 3.71, 4.00
Raising Arizona (1987), 3.62, 4.00
Being There (1979), 4.30, 5.00
Truth About Cats &amp; Dogs, The (1996), 3.61, 4.00
</pre>

<h2 id="conclusion">Conclusion:</h2>

<p>In this post, I have outlined some of the steps used in typical recommendation systems.  We have discussed the difference between content-based filtering and collaborative-based filtering. From there, we took a look at some of the math (Pearson’s correlation) and also how Singular Value Decomposition can be used to generate recommendations.  Lastly, we took a look at how the Surprise package in python can be used to easily implement a recommender system based on movie scores.</p>

<p>It should be mentioned here that the approach above is based on solving the user item matrix.  Other approaches also exist, including using deep neural networks.  I will save that discussion for another day.</p>

<p>I hope you have enjoyed this post!  Until next time…</p>

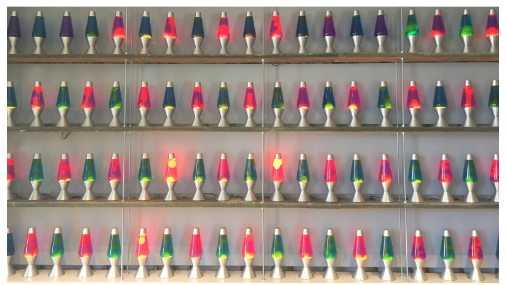
<p>Miles</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[A mere mortals guide to collaborative filtering.]]></summary></entry><entry><title type="html">Something Random</title><link href="/general/2023/11/23/data_science_37.html" rel="alternate" type="text/html" title="Something Random" /><published>2023-11-23T08:09:00+00:00</published><updated>2023-11-23T08:09:00+00:00</updated><id>/general/2023/11/23/data_science_37</id><content type="html" xml:base="/general/2023/11/23/data_science_37.html"><![CDATA[<p><img src="/images/cloud_flare_lava_lamps.png" alt="Cloudflare Lava Lamps" /></p>

<p><a href="https://www.cloudflare.com/learning/ssl/lava-lamp-encryption/">Source</a></p>

<p>Recently, I came across a (very short) book by Andy Weir called Randomize.  You can <a href="https://www.amazon.com/Randomize-Forward-collection-Andy-Weir-ebook/dp/B07VDJBKNJ">get if for free from Amazon</a>.  I won’t spoil it for you, but a main theme in the book is random numbers… or really the illusion of random numbers when it comes to computers.</p>

<p>When I was reading this book (short story might be a better description), it occurred to me that infinity is to calculus what randomness is to statistics and probability.  To clarify, being able to compute integrals and derivatives require the ability to handle and manipulate calculations involving infinity.  In probability and statistics, we are often faced with random variables, and chance.  In order to compute probabilities and confidences, we must be able to handle and manipulate calculations involving randomness, and random distributions of various types.  And, just as in calculus and mathematical analysis where we have different kinds of infinity (countable vs uncountable), there are also different kinds of distributions of random numbers.</p>

<h2 id="not-all-random-is-the-same">Not All Random is the Same</h2>

<p>Statistics is the study of the properties of samples and using that information to make statements about populations.  When people say “Pick a random number between 1 and 100…”, what they typically mean is to pick an integer between 1 and 100, inclusive, where each number has the same chance of being chosen.  It turns out that there are other ways to pick random numbers, however.  Consider this variation on the “Pick a number between 1 and 100 game.”</p>

<p>Pick 30 random numbers between 1 and 100, and compute their average and do that over and over again 100 times and write down the averages.”  The list that you write down will be random… but it is a special kind of random. The <a href="https://sphweb.bumc.bu.edu/otlt/mph-modules/bs/bs704_probability/BS704_Probability12.html">Central Limit Theorem</a> of statistics tells us that the list of 100 averages will follow a normal distribution.  (The CLT requires that the samples must have a sufficiently large sample size, usually n&gt;=30.)</p>

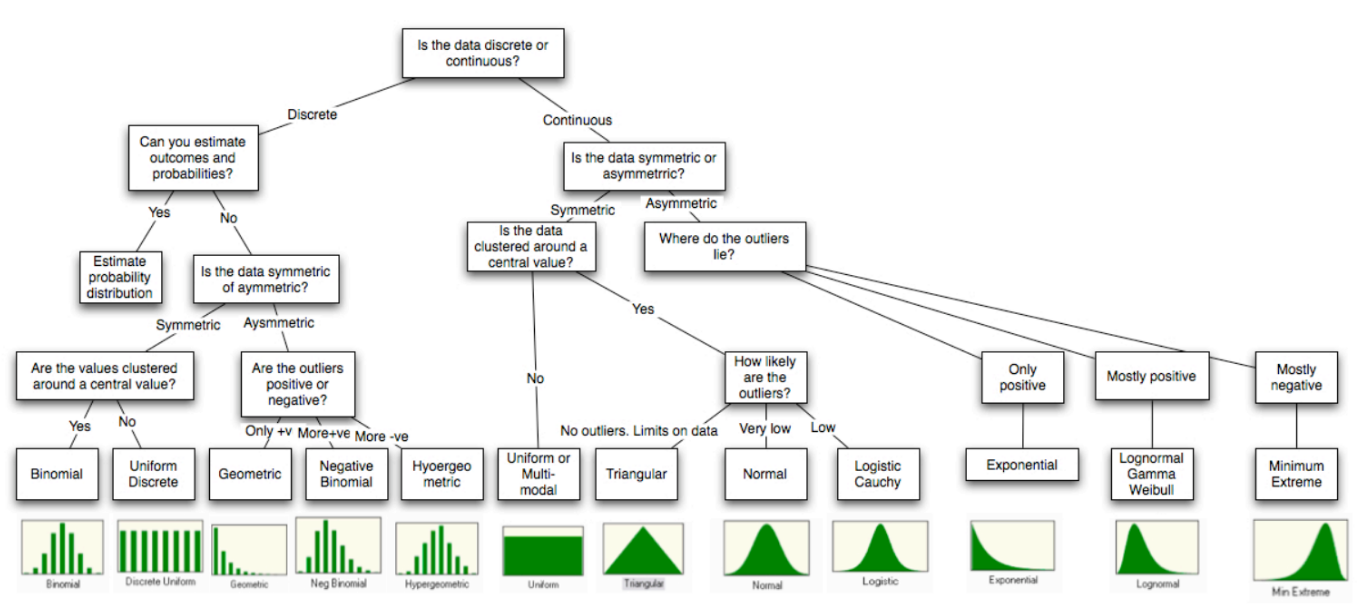
<p>What we are touching on here is the idea of distributions of random numbers.  If I say pick a random number between 1 and 100, that is called a “uniform” distribution.  However, when I look at the means, I am starting to approximate a different kind of random distribution called a “normal distribution”.  There are many other kinds of random distributions.</p>

<p><img src="/images/random_distributions.png" alt="Random Distributions" />
<a href="https://pages.stern.nyu.edu/~adamodar/pdfiles/papers/probabilistic.pdf">Source.</a></p>

<h2 id="stochastic-vs-deterministic">Stochastic vs Deterministic</h2>

<p>Random numbers underlie the concept of stochastic models and optimization.  Random, or “stochastic” models stand in contrast to what is often referred to as “deterministic” models, which use a direct approach.  To understand the difference, consider two methods for estimating Pi.  The method that Archimedes used, which involves <a href="https://arxiv.org/pdf/2008.07995.pdf">circumscribing triangles inside of a circle</a> would be considered deterministic.  In the Archimedes algorithm, you don’t need any kind of randomness to do the calculations.</p>

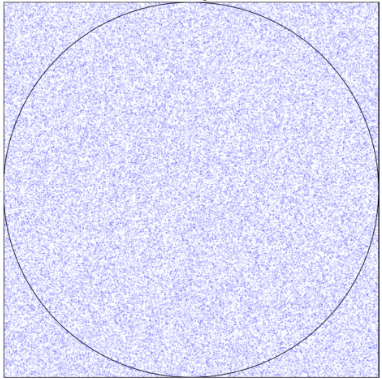
<p>In contrast, the so-called “Monte Carlo” method involves randomly adding dots to a square with a circle enclosed inside.</p>

<p><img src="/images/pi_monte_carlo.png" alt="Pi Monte Carlo" /></p>

<p>In this approach, you add as many random dots as you would like, and then count those that fall inside the circle.  You can then use this formula to get an estimate for Pi.</p>

\[\pi \approx 4 ( \frac {num\_points\_in\_circle} {total\_num\_points})\]

<p>This approach is considered stochastic as it requires the use of random numbers for the simulation to work.</p>

<p><a href="https://bookdown.org/manuele_leonelli/SimBook/a-bit-of-history.html">Similar techniques were used by John von Neumann and Stanislaw Ulam to solve problems related to radiation while working on the Manhattan project.</a></p>

<h2 id="good-random-vs-bad-random">Good Random vs Bad Random</h2>

<p>“True” random numbers are not predictable.  Also, sequences of true random numbers are not generally repeatable on demand.  Stochastic algorithms would not be repeatable if they relied on truly random numbers.  And, without repeatability, algorithms that use stochastic processes would be very difficult to test and results would be impossible to confirm.</p>

<p>Digital computers are deterministic machines. Digital circuitry alone is not capable of creating truly random numbers (unless it is malfunctioning).  Nature, however, is full of sources of randomness. To come up with true random numbers computers use devices called true random number generators or TRNGs.  These devices usually involve some physical and analog source of entropy.  True random number generators play a critical role when it comes to cybersecurity. An interesting example of one elaborate TRNG was created by the cybersecurity company Cloudflare in 2017.  <a href="https://www.cloudflare.com/learning/ssl/lava-lamp-encryption/">You can read more about it here</a>. For simplicity, speed and repeatability, computers typically rely on algorithms called pseudo-random number generators, often called PRNGs.  PRNGs involve a random seed to start with.  We will see some examples next.</p>

<p>IBM developed a PRNG in the late 1960s called RANDU.  This once highly regarded PRNG used this formula:</p>

\[V_{j+1} = V_j mod 2^{31}\]

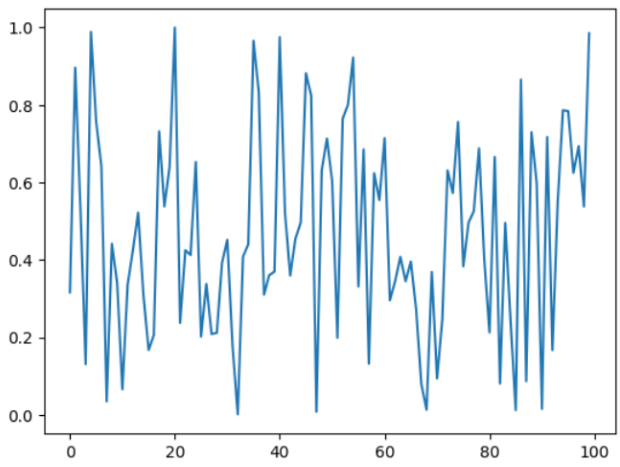
<p>Known as a linear congruential generator, or LCG, the above sequence provides seemingly random numbers as shown below (scaled to between 0 and 1).</p>

<p><img src="/images/randu.png" alt="Randu" /></p>

<p>One advantage of RANDU was that it was very fast to compute.  However, to see the weakness of RANDU, consider each three consecutive values as coordinates in 3 dimensional space.  The following animation shows the obvious issue RANDU has.</p>

<iframe width="883" height="625" src="https://www.youtube.com/embed/rVWv8Qj7yEE" title="RANDU" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" allowfullscreen=""></iframe>

<p>In addition to the clearly anti-random 3-dimensional distribution of RANDU, the PRNG also suffers from other issues. The following article does into detail on examining RANDU.</p>

<p><a href="https://bkamins.github.io/julialang/2020/12/31/randu.html">https://bkamins.github.io/julialang/2020/12/31/randu.html </a></p>

<h2 id="randomness-and-regression">Randomness and Regression</h2>

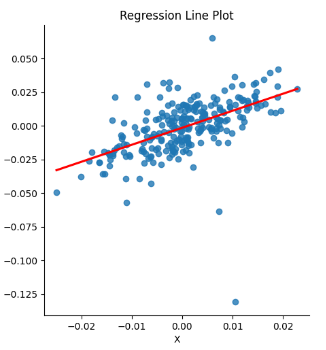
<p>Randomness and normal random variables play an important role in regression, particularly when it comes to goodness of fit.  Simple linear regression can be thought of as a best fit line thru a collection of datapoints.</p>

<p><img src="/images/regression1.png" alt="Regression" /></p>

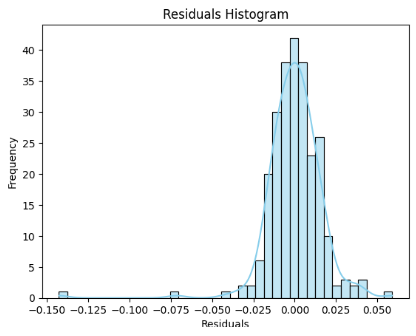
<p>When we do a regression, one of the things that we pay special attention to is the difference between the original data points that we are trying to fit a line thru, and the difference between those points and the best fit line.  These differences are referred to as the “residuals”.  When we do regression, if we can show that the residuals are normally distributed, it opens up the opportunity to make statements about how well our regression line fits our data. To make our statements, we need the residuals to be independent from each other and all the residuals need to follow the same distribution.  If this happens, we can state how well we expect our regression model to do in inference.  This, by extension, makes it possible for us to create confidence intervals around our regression line.  Having a “well fit model” also makes it possible for us to make statements about our confidence in the values of our regression model coefficients.</p>

<p><img src="/images/residuals1.png" alt="Residual Histogram" /></p>

<h2 id="random-means-not-predictable">Random Means Not Predictable</h2>

<p>At Georgia Tech, I took a class on business analytics.  It was an interesting, if not a bit scattered course, that covered aspects of finance, digital marketing, and a number of other topics.  One of the best things about the class was the book… that we never used.  (Not sure why.)  The book was “Data Mining for Business Analytics”.  ISBN:  978-1-118-87936-8 by Shmueli, Bruce, Yahav, Patel, and Lichtendahl.</p>

<p>Towards the end of the book, there is this quote…  “Before attempting to forecast a time series, it is important to determine whether it is predictable, in the sense that its past can be used to predict its future beyond the naive forecast.”</p>

<p>In other words, sometimes things are just random based on what you know.  DON’T WASTE TIME TRYING TO PREDICT THEM!</p>

<p>A time series where each term is the previous term plus some random noise is known as a “random walk”.</p>

\[X_{n} = X_{n-1} + \epsilon\]

<p>It turns out that there is a really easy technique to determine if a time series is a random walk, which involves fitting an AR(1) model.  An AR(1) model (or ARIMA(1,0,0)) is simply a regression model where each term in the sequence is regressed back on the previous term.  In other words, take all the pairs in the time series defined by:</p>

\[(X_n, X_{n-1})\]

<p>If the slope of a regression line fit to the above pairs is 1, we have shown that the sequence is a random walk.  Since this is a regression model under the hood, we can also look at the P-value for the coefficient in the underlying model to get a sense of how reliable that coefficient is.  As we mentioned before, making those “goodness of fit” statements relies on the fact that the residuals are independent and identically distributed.  While the values in our time series are NOT independent (each step in the time series depends on the last one), the difference between two successive steps should be.  To see why, look at the definition of a random walk, and move the $ X_{n-1} $ term to the left side of the equation.</p>

\[X_n - X_{n-1} = \epsilon\]

<p>In the above, $ \epsilon $ represents random noise.</p>

<h2 id="an-example">An Example</h2>

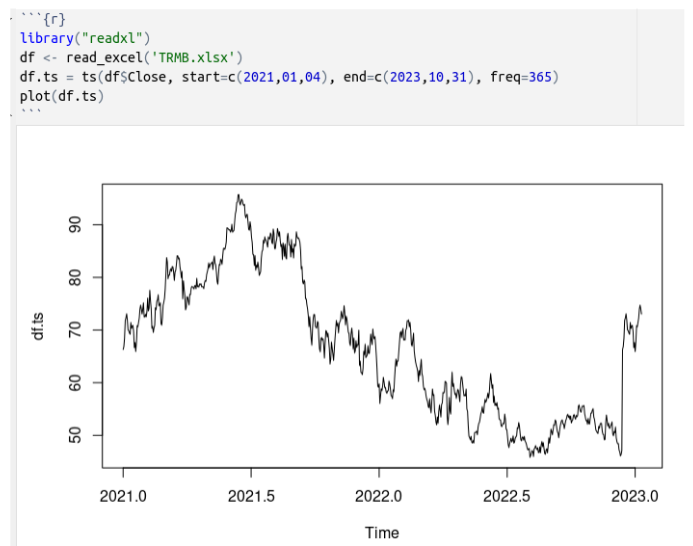
<p>Here is an interesting example.  Below, I have taken the daily closing values of a company’s stock from Jan 1, 2021 thru Oct 10, 2023.</p>

<p><img src="/images/trimble_walk_1.png" alt="Trimble image 1" /></p>

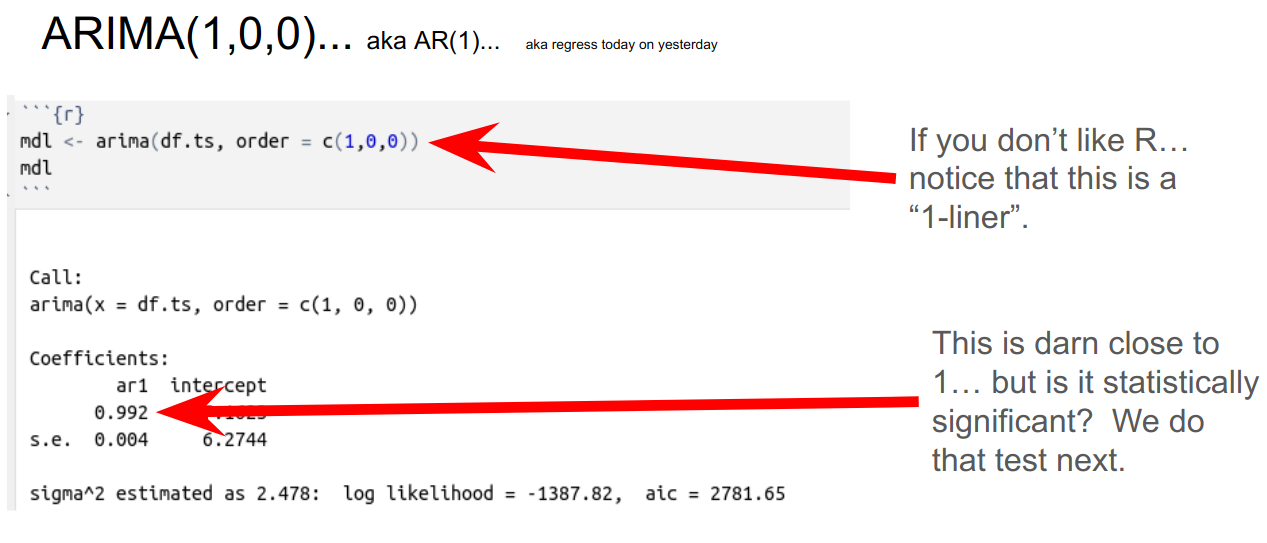
<p>Next, using the R programming language, I have fit an ARIMA(1,0,0) model (aka AR(1) as mentioned above) to the data.</p>

<p><img src="/images/trimble_walk_2.png" alt="Trimble image 1" /></p>

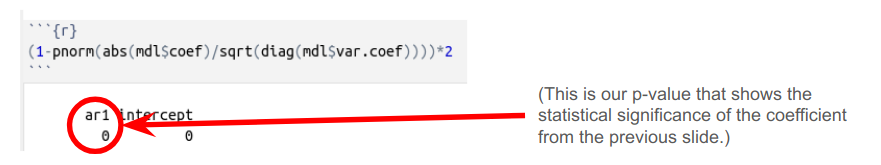
<p>As illustrated above, the coefficient is really close to 1.  Continuing on to check the statistical reliability of the coefficient in the model, the P-value is nearly zero.  This means that the coefficient is highly reliable and we are looking at a random walk.</p>

<p><img src="/images/trimble_walk_3.png" alt="Trimble image 2" /></p>

<p>The bottom line here is that we have shown the stock above to be an essentially unpredictable random walk.  Any efforts to fit a model based on JUST THIS DATA is not going to work.  Now, that does not necessarily mean that we couldn’t find a different model with different predictor variables.  It just means that the sequence itself is not enough to go on when trying to do predictions.</p>

<h2 id="conclusion">Conclusion</h2>

<p>So, the takeaways from this post are:</p>

<ol>
  <li>Random is to stats what infinity is to calculus.</li>
  <li>There are good random (estimate pi and lava lamps) and bad random RANDU.</li>
  <li>There are different kinds of random (distributions).</li>
  <li>Randomness underlies our ability to state the statistical significance and confidence intervals of regression.</li>
  <li>Some stuff is just random, so don’t waste your time trying to predict it.</li>
</ol>

<p>I hope you have enjoyed this long overdue post.  I wish everyone a wonderful holiday season, and a happy new year!</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">Azure ML? Seriously? Yes. Seriously!</title><link href="/general/2022/06/28/data_science_36.html" rel="alternate" type="text/html" title="Azure ML? Seriously? Yes. Seriously!" /><published>2022-06-28T08:09:00+00:00</published><updated>2022-06-28T08:09:00+00:00</updated><id>/general/2022/06/28/data_science_36</id><content type="html" xml:base="/general/2022/06/28/data_science_36.html"><![CDATA[<h1 id="introduction">Introduction</h1>

<p>I have been working full time on Data Science since mid 2017 (5 years).  During that time, I have made just about every ML mistake you can think of.</p>
<ul>
  <li>Use training data in the test set?  Yup.</li>
  <li>Created a great deep learning model only to loose track of the model file and have to retrain?  Sure.</li>
  <li>Tried to retrain a model, but couldn’t re-find the hyperparameters that worked well?  Done that.</li>
  <li>Used an open source autoML package that was based on Java and used Log4J that was shown to have major security flaws and then forced to retrain the autoML model again, but I still cannot remember what the first autoML model settled on?  Yeah.</li>
  <li>Ran an inference model on a bare-metal EC2 instance that mostly sat idle, but has to have a boatload of RAM so it is way more expensive that it should be, even if it only “wakes up” part of the time.  Yeah.</li>
</ul>

<p>Heck, I am not proud, I can even say that I wrote a MONSTER single-threaded-and-super-slow python app that sucks data out of a cloud data service, chugs on it, and then shoves the results back into the cloud data service… from scratch.</p>

<p>So, yeah.  I have made a ton of mistakes.  In December, I completed my MS in Analytics from Georgia Tech.  (See my earlier post.) That program helped me begin to understand what professional analytics is about.  It turned me onto techniques like EDA, simulation, cross-validation, and feature engineering.  I learned and relearned about the math and statistics of why things work, and why they sometimes don’t.  My masters courses also helped me learn about behaviors and best practices that help reduce the likelihood of making process and workflow mistakes.  But, even after all that, doing analytics and data science is hard.  Doing it well, is very hard.</p>

<p>I am so happy that Microsoft has helped make it a little easier.</p>

<p>Now, if you would have said to me that I would write that line 5 years ago, I would have said you were crazy.  I have used Microsoft products in the past, but it has always been with some reluctance.  I don’t typically run Windows unless I cannot avoid it (I prefer to use Linux, or a Mac.)  Being a certified Novell Network Engineer (CNE… you young kids can just Google that), I never quite got over the fact that Microsoft basically killed Novell.</p>

<p>I was somewhat skeptical when, in my current job, I found myself faced with evaluating Azure ML.  I must say that Microsoft has done a very nice job of Machine Learning Platform as a Service.  Add to that how far Azure has come…  Well, if you’re working in Analytics or Data Science, it might be well worth your time to check out the platform.  And… you can try it out for free!</p>

<p>Still need to be convinced why MSFT has developed a winning solution for analytics?  Ok.  I respect that.  Let me offer a few details to consider.  I’ll break this down relative to how I tend to think of the analytics process…</p>

<ul>
  <li>Data</li>
  <li>Exploratory Analysis</li>
  <li>Model Training</li>
  <li>Experiments</li>
  <li>Model Training With MASSIVE Data</li>
  <li>Model Management</li>
  <li>Model Deployment and…</li>
  <li>Data</li>
</ul>

<p>That said, lets begin with data…</p>

<h1 id="data">Data</h1>

<p>As you maybe guessed from the above, I believe that data science and analytics literally begin and end with data.  It is really crazy to me how so many data science platforms don’t really do data justice.  Azure ML has this covered by seamlessly integrating data into the ML environment.  You can see this in the Azure ML Studio.  If you are not familiar with Azure, and are with AWS (as I was) it works in sort of the same paradigm.  Azure has a TON of services that they offer through their portal.  (My favorite joke about AWS is that if Voldermort really wanted to hide a horcrux, he would have done it in the AWS portal.)  Azure ML Studio makes using the various services involved in Azure ML easy.  They have really simplified the “searching for the horcrux” problem well with ML Studio.</p>

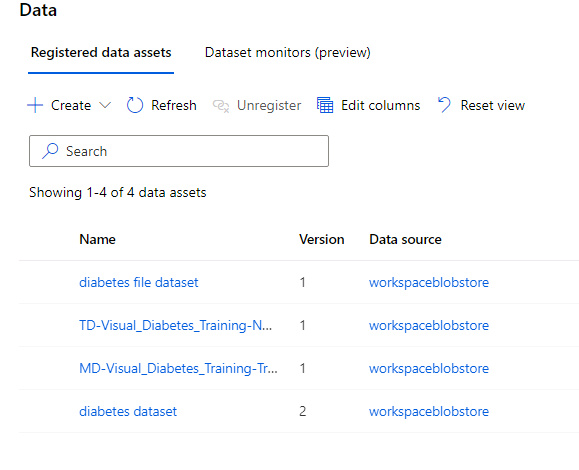
<p><img src="/images/az_data.png" alt="Azure Data" /></p>

<p>Accessing data in Azure is done with datastores and datasets.  Datastores provide seamless access to data hosted in Azure in the form of blob storage, files, data lakes, SQL, Postgres and MySQL databases.  Datasets are versioned sets of data used primarily for training models.  ML Studio makes it seamlessly easy to find and use data you need for training models.  I really like the fact that can VERSION data sets.  Knowing what DATA you used to train a model is critical.  Change the training data, and of course you are going to change the model.  This is something that I don’t think is addressed enough.  Sure, it is important to know your model hyperparameters… but what DATA you use to train the model is an equally important question.</p>

<h1 id="exploratory-analysis">Exploratory Analysis</h1>

<p>Once you have data, a critical first step is to actually look at it.  This is something that was really stressed in several of my Masters classes, and I agree.  Don’t just assume that your data file is correct.  ACTUALLY LOOK AT IT.  This is easy in Azure ML Studio.</p>

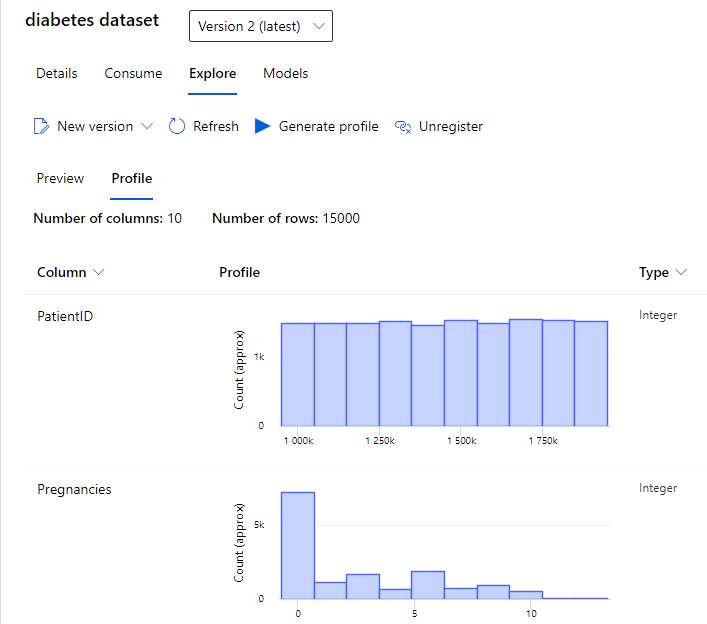
<p><img src="/images/az_eda.png" alt="Azure EDA" /></p>

<p>If you’ve imported the data, you can simply view the data.  You can also generate a dataset profile, which will provide some nice basics descriptive statistics and graphs for your data set.  You could do this in a jupyter notebook easily enough… but with Azure, you don’t even have to do that.</p>

<h1 id="model-training">Model Training</h1>

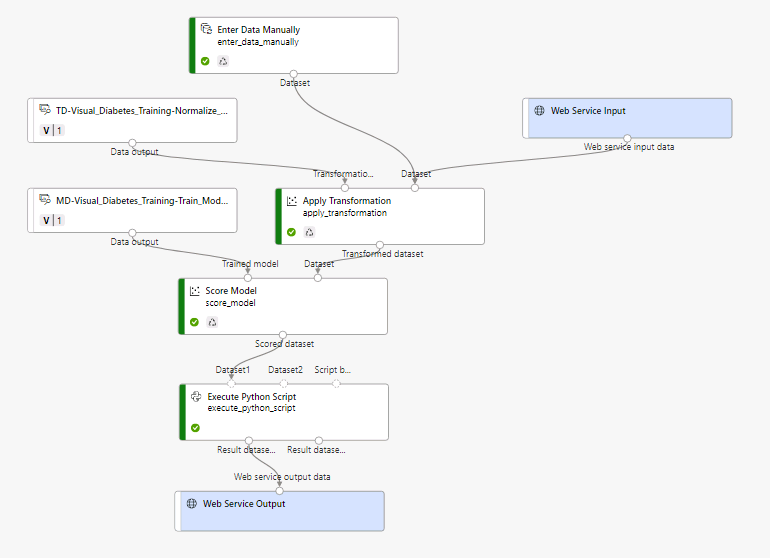
<p>Once you have understood your data, you will eventually want to start building some models.  Azure ML Studio uses the Jupyter notebook paradigm.  You can mix code and documentation in these notebooks as you would expect.  The other option with Azure is to use their “no code” (which is really low code) training pipeline “Designer”.  I remember when we looked at this in grad school, and one classmate commented on just how easy and intuitive using the Azure ML designer was for this purpose.</p>

<p><img src="/images/az_designer.png" alt="Azure Designer" /></p>

<p>If you are looking to build a simple regression model, or a K-MEANS, or even a boosted tree model, the designer works very well.  It also helps prevent mistakes like forgetting to USE THE SAME DATA CLEANING on your inference data that you used on your training data.  (This is another data science anti-pattern that I have screwed up on in the past.)</p>

<h1 id="experiments">Experiments</h1>

<p>As I mentioned before, one of the key behaviors of a data scientist is keeping good records of what version of a model was trained on what data with what hyperparameters and what the resulting accuracy metrics were for the testing data.  IMO, this is a key differentiator between a professional data scientist, and a citizen/amature data scientist.</p>

<p>There is another really interesting aspect to experiments in Azure ML.  An Azure ML experiment can be created, and then ran and re-ran programatically.  This opens up a great way to “script” machine learning training.  To make this work, the training process needs to be captured in an .py file.</p>

<pre>
from azureml.core import Experiment, ScriptRunConfig, Environment
from azureml.core.runconfig import DockerConfiguration
from azureml.widgets import RunDetails

# Get the workspace
ws = Workspace.from_config()

# Create a Python environment for the experiment (from a .yml file)
env = Environment.from_conda_specification("experiment_env", "environment.yml")

# Create a script config
script_config = ScriptRunConfig(source_directory=training_folder,
                                script='diabetes_training.py',
                                environment=env,
                                docker_runtime_config=DockerConfiguration(use_docker=True)) 

# submit the experiment run
experiment_name = 'mslearn-train-diabetes'
experiment = Experiment(workspace=ws, name=experiment_name)
run = experiment.submit(config=script_config)

# Show the running experiment run in the notebook widget
RunDetails(run).show()

# Block until the experiment run has completed
run.wait_for_completion()
</pre>

<p>Check out the full code here for an example:  https://github.com/MicrosoftLearning/DP100/blob/master/03B%20-%20Training%20Models.ipynb</p>

<p>Azure ML allows you to use either Azure’s own experiments framework, or ML Flow.  ML Flow is an opensource project developed by Databricks.  That said, it seems to me that the Azure framework provides a nicer UI, and more complete functionality.  I have attempted to use MLFlow in the past, and it doesn’t do well in corporate environments with complex network topologies.  Plus, MLFlow requires you to run an MLFlow server…  why do that when Azure essentially offers better functionality without the headache of running a python based server.</p>

<h1 id="model-training-with-massive-data">Model Training with MASSIVE Data</h1>

<p>Training and working with big data is a special challenge in Analytics.  There are a number of different approaches including downsampling the data, or trying to scale up the compute.  But, what do you do if you come across a dataset that is multiple terabytes or petabytes?  An answer to this problem can be found in cluster computing, and Apache Spark is the leading opensource project in this area.  Unfortunately, Apache Spark is notoriously difficult to configure and run.  The complexities of running computing clusters where worker nodes alll have to be coordinated is a challenging task.  AWS attempts to address this problem with ther EMR (Elastic Map Reduce) service… unfortunately that too can be very challenging to get working and very difficult to troubleshoot when it doesn’t.  Databricks is a Spark as a Service offering (and company) that makes running Spark very easy.  Databricks also offers data storage solutions that work well with their enhanced Spark solution that makes a ton of sense.</p>

<p>Now, the really nice thing about Databricks is that it is actually contained in azure, and accessible from Azure ML Studio…</p>

<p><img src="/images/az_databricks.png" alt="Azure Databricks" /></p>

<p>Azure Databricks is part of the Azure ecosystem, and so it is billed through your Azure account (essentially as a “pay as you go” databricks subscription.)  I cannot overstate the value of Databricks when it comes to processing huge data.  Historically, Databricks was used for ETL tasks and large scale data engineering.  However, it can also be used for machine learning tasks.  Databricks has its own ML libraries that take advantage of the underlying Spark infrastructure which makes training models on huge datasets practical.  Databricks also works efficiently with the underlying Spark compute clusters (which it gets from Azure compute), and allows you to scale down these clusters when they are not used.  But, don’t forget to make sure that option is set because, trust me on this, there is no faster way to create a big compute bill than bring up a gigantic cluster and forget to shut it down over the weekend!</p>

<h1 id="model-management">Model Management</h1>

<p>Training models is the fun part of data science and analytics, and models that have been trained are assets.  A lot of time and effort go into creating models, and that investment is manifest in the trained model artifact.  That is why, from a business perspective, it is absolutely imperative that trained models are organized, currated, and the data associated with those models isn’t lost.  A huge part of doing data science is running experiments, and seeing if new approaches to solve a data problem result in better results.  But, how can you know what a better result is if you cannot put your finger on what your current model’s accuracy was when you trained it?  Azure ML does an excellent job of helping not only keep track of models, but providing a way to walk back from a model running in production, to the description of the how the model was trained, to the actual code that trained the model, the data that it was trained on, and the hyperparameters associated with the training.  This is all part of Azure model management and azure deplopyments.</p>

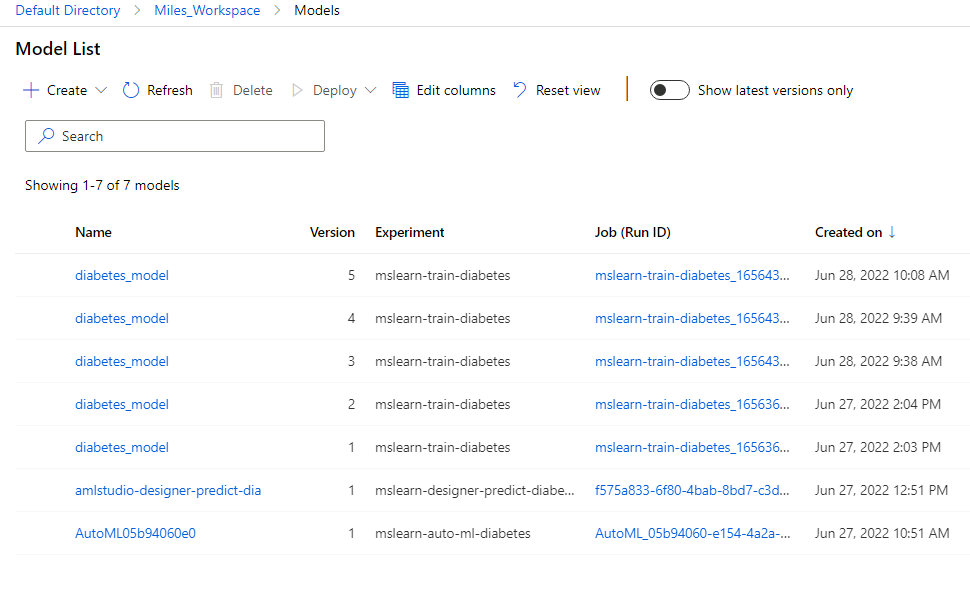
<p><img src="/images/az_models.png" alt="Azure Model Management" /></p>

<p>I think that model management is something that is difficult to fully appreciate until you are faced with it in real life.  In my early days of messing around with deep learning, I trained a model that had some really good results.  At least, I seem to remember that it had really good results.  After running the model in production for a few months, someone asked me what the training accuracy was.  (Precision, Recall, F1, etc.)  I didn’t have that information stored anyway, but I didn’t think it would be a problem.  I would just retrain the model.  I was shocked when I saw my metrics after re-training.  They were nowhere close to what I remembered.  I tried and tried, but I could never find the right combination of learning rate, optimizer, etc. that gave me what I needed.</p>

<p>Again, don’t be “ME”!  Keep track of your models and you results.  This is the path to enlightenment, and Azure ML makes this so easy.</p>

<h1 id="model-deployment">Model Deployment</h1>

<p>Once you have a model trained, and the accuracy is acceptable, you are good to go!  Except that you are not.  You are actually not going anywhere.  It is like running 26 miles in a marathon, and not finishing the last 0.2 miles.  Deploying the model is how you leverage the investment that you made by collecting and cleaning data, running experiments, and keeping track of results.  If you don’t somehow get that model into a workflow within your organization, you have essentially just wasted a TON of effort.</p>

<p>Unfortunately, for most data scientists, that last 0.2 miles of the marathon is a merciless uphill climb.  And, for how clever we thought we were with our elastnet feature selection, and our autoregressive integrated moving averages, and our eigenvectors and principal component analysis, we are left staring blankly at a docker build file that just makes no damn sense.  DevOPs is a (black) art… at least to a data scientist.  And… thank the maker for Azure endpoints.  Azure ML provides a very straight forward way to deploy models into production.  This can be done on a single compute instance, or into a kubernetes cluster, all automatically.  The management tools are all there for monitoring the models.  The security protocols have all been worked out so you don’t have to reinvent the wheel and fight tooth and nail with JWTs and OAUTH…  unless you want to.  And if you do, bless you.  The approach also allows you to deploy models not only into production but also on your own workstation via Docker.</p>

<p><img src="/images/az_endpoint.png" alt="Azure Endpoints" /></p>

<p>It is important to keep in mind that when you deploy a model, someone is going to call it.  And, if they call it, they are going to pass in data and expect a result.  That input and output data is another resource.  It contains information about your customer and may yield insights. And, so we return back right to where we started…</p>

<h1 id="and-it-all-comes-back-to-data">(And it all comes back to) DATA</h1>

<p>When a model is deployed in Azure ML, you have the option to capture insights from the model running in production.  Turning on insights will allow you to capture data and metrics for how people are using the endpoints you have created.  This is incredibly valuable.  The distribution of the OUTPUT of you models is also extremely important.  Most models are trained once, and then used over and over.  They essentially know their world for a single point in time.  However, the universe continues to change.  As a result, the longer you run a model in production, the results will start to drift.  This means that your model will, over time, become less and less reliable at describing, predicting and prescribing things based on inputs.  It is important to watch the distribution of our models outputs in order to know where and how things are changing.  Azure ML application insights allows for data capture and monitoring of model inputs and outputs.</p>

<h1 id="a-few-comments-about-the-future">A Few Comments About “The Future”</h1>

<p>Azure ML Studio isn’t the only way to work with Azure.  Microsoft has developed a fully functional SDK that can be used to configure and manage ML data, components, models, experiments, etc.  As companies develop more ML models, keeping track of those models will only increase in complexity.  Leveraging scripts are a good way to help keep this managable.  This is one of the main ideas behind MLOps.  I think that the cohesive SDK that Microsoft has developed is particularly valuable in this regard.  That said, I appreciate having a GUI available that allows me to focus on solving the problems and not on trying to remember SDK classes and methods.  So, there is a balance that needs to be struck.  From what I can see, it seems that Microsoft is doing a good job in that regard.</p>

<h1 id="conclusion">Conclusion</h1>

<p>I hope this post has highlights some of the key benefits of running Azure ML.  I only touched on a few of them here.  I would encourage anyone who hasn’t done so and considers themself a data scientist to check out the Azure ML offering.  You can sign up for a free account with $200 credit.  The account gives you 30 days to play with Azure ML.  The registration does require a credit card, but they will not automatically start charging you when you run out of credits.  (At least that is the message you receive when you sign up.)</p>

<p>I think you’ll be impressed by Azure ML.  Seriously.</p>

<p>Regards,</p>

<p>Miles</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Introduction I have been working full time on Data Science since mid 2017 (5 years). During that time, I have made just about every ML mistake you can think of. Use training data in the test set? Yup. Created a great deep learning model only to loose track of the model file and have to retrain? Sure. Tried to retrain a model, but couldn’t re-find the hyperparameters that worked well? Done that. Used an open source autoML package that was based on Java and used Log4J that was shown to have major security flaws and then forced to retrain the autoML model again, but I still cannot remember what the first autoML model settled on? Yeah. Ran an inference model on a bare-metal EC2 instance that mostly sat idle, but has to have a boatload of RAM so it is way more expensive that it should be, even if it only “wakes up” part of the time. Yeah.]]></summary></entry><entry><title type="html">What is Past is Prologue. Reinforcement Learning meets Time Series Classification</title><link href="/general/2022/02/20/data_science_36.html" rel="alternate" type="text/html" title="What is Past is Prologue. Reinforcement Learning meets Time Series Classification" /><published>2022-02-20T08:09:00+00:00</published><updated>2022-02-20T08:09:00+00:00</updated><id>/general/2022/02/20/data_science_36</id><content type="html" xml:base="/general/2022/02/20/data_science_36.html"><![CDATA[<h1 id="reinforcement-learning-meets-time-series-classification">Reinforcement Learning meets Time Series Classification</h1>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>What is past is prologue.  (Shakespeare, The Tempest, 1.2)
</code></pre></div></div>

<h2 id="introduction">Introduction:</h2>

<p>Everything that happens in our reality happens in the context of time.	 And, knowing some discrete or continuous measure of something is only meaningful in the context of when that measurement was taken.  For example, consider $1000.  That number means something very different today than it did in 1822. Because we exist, trapped in the constant flow of time, knowing what is comming next, or classifying what is happening in the present are highly valuable to us. It is of little wonder that finance, autonomy, and natural science are filled with problems related to time series analysis.  It is ironic that, despite the fact that we live surrounded by problems involving time series, no uniform python packages have existed for time series modeling.  While scikit-learn does offer some tools, those tools are very limited.  In 2019, Franz Király, Markus Löning, Anthony Bagnall and Jason Lines began work on a python framework intended to follow the scikit-learn interfaces.  Their framework includes tools and models for classification, forecasting, annotation, regression, and more.  This post explores some of the tools provided in the sktime package for time series classification.  It is worth noting that sktime goes far beyond just time series classification and includes tools for time series transformers, forecasting, and more.</p>

<h2 id="time-series-classification">Time Series Classification</h2>

<p>So, what is time series classification?  To begin with, we should probably define what a time series is.  The term is almost completely self defining.  In their book “Time Series Analysis and Its Applications” by Shumway and Stoffer (ISBN: 978-3-319-52452-8), the authors refer to time series as “…data that have been observed at different points in time.”  (Note, the entire first chapter of this book is an excellent resource covering many topics and examples in this field of study.)  A slightly more detailed definition comes from the <a href="https://www.itl.nist.gov/div898/handbook/pmc/section4/pmc41.htm">NIST Engineering Statistics Handbook</a>:  “An ordered sequence of values of a variable at equally spaced time intervals.”</p>

<p>Mathematically, the definition of a time series can be written as:</p>

<p>$ y_t $
 where
 $ t=(…-2,-1,0,1,2…) $</p>

<p><a href="https://hughchristensen.com/papers/academic_papers/Prado.West.06.pdf">Source: Time Series Modelling, Inference and Forecasting by Prado and West</a>.</p>

<p>According to Alexandra Amindon, Time series classification asks the question “Given a set of time series with class labels, can we train a model to accurately predict the class of new time series?”  Amindon has written an excellent blog post on this subject on <a href="https://towardsdatascience.com/a-brief-introduction-to-time-series-classification-algorithms-7b4284d31b97">towardsdatascience.com</a>.</p>

<p>Our goal here, however, is not to re-hash this excellent work, but rather to apply several time series classification algorithms offered by sktime on a particular time series classification problem.</p>

<h2 id="simulated-problem">Simulated Problem:</h2>

<p>Time series classification, as the name implies, is a machine learning task that involves creating a model that can classify different time series into specific sets.  In the movie, “The Hunt for Red October”, the characters in a submarine identify a sound made by another submarine.  Their task is to identify the type of submarine based on the sound it makes.  In this case, analyzing a discrete Fourier transformation of the sound would probably work well because the sound of the submarine propellers are very cyclic.</p>

<p>Now, let’s consider a different, and likely more difficult problem.  What if we had a spaceship that was attempting to land on the surface of the moon.  Our goal was to identify who was flying the spaceship based on the trajectory that the ship had while landing.  This problem would be significantly more difficult than the submarine example simply because the trajectory would appear much more varied.  To explore this specific problem further, it is possible to simulate the scenario of landing a spaceship on the moon, and training different “agents” as pilots.</p>

<h2 id="reinforcement-learning">Reinforcement Learning:</h2>

<p>The OpenAI Gym provides a rich set of simulated environments that can be used to simulate/generate time series data.  Once such environment is the “Lunar Lander” game.  In this game, the goal is to safely land a simulated lander module on the surface of the moon.  The simulation takes place in a simplified 2-Dimensional space.  The game starts with a lunar lander module some distance above the surface of the moon.  The player (agent) then uses thrusters (left, right, and up) to guide the lander to a pre-determined landing zone.</p>

<p><img src="/images/lunar_lander.gif" alt="'AI Gym Lunar Lander'" /></p>

<p>For all those millennials out there, trust what many of us born before 1975 already know.  The task is much harder than it sounds!</p>

<p>The objective of the OpenAI gym environment is to provide an environment that can be used to train reinforcement learning models. The reinforcement learning model used for this project is a Deep Queue Network or DQN.</p>

<p>It should be noted that, in this case, the DQNs fly the lander based on a parameterized subset of the environment “state”, which includes the location and angle of the lander.  (Note that the lander will rotate when the lateral thrusters are applied). This approach of using parameterized values is somewhat different from other reinforcement learning models that use the graphical representation of the game “screen.”  Using the parameterized values reduces the dimensionality of the problem space considerably, and reduces the time required to train the model.</p>

<p>The <a href="https://gym.openai.com/envs/LunarLander-v2/">OpenAI Gym Lunar Lander</a> code is part of the OpenAI Gym project and is opensource and freely available.  More information about the <a href="https://pytorch.org/tutorials/intermediate/reinforcement_q_learning.html">PyTorch DQN</a> is available on their website as well.  While it would be tempting to dive into these resources further, we will continue to just focus on the time series data generated by the agents trained using these tools and techniques.  Code for the neural networks is available at the link at the end of this post.</p>

<h2 id="the-data">The Data</h2>

<p>As missions are flown by the novice and expert agents, the state values of the game are saved.  Each mission is saved as an individual file.  Each of these files, then, can be thought of as a  multidimensional time series.  For the purposes of this paper, we looked specifically at just two parameters of the state, specifically the X and Y values of the lander.  The goal of this paper was to focus just on univariant time series data.  Therefore, it is necessary to take the X and Y values and somehow map them into a single value.  In order to create this mapping, we first derive the velocity of the lander in the X and Y directions. Once the velocity has been calculated, the magnitude of the velocity M of the lander is calculated based on the simple formula</p>

<p>M = sqrt(X^2 + Y^2)</p>

<p>Where X and Y are the velocity in the X and Y directions.</p>

<p>It is possible to use the same approach on the change of the velocity of the lander.  This, of course, is the lander’s acceleration.  It is also possible to use the same approach on the change of acceleration of the lander.  The change of acceleration is also commonly referred to as the “Jerk”.  For this exercise, velocity returned the best results.</p>

<p>Here is an example of the velocity for a random novice and random expert flights.  Here the novice flight was flown by an agent that had 300 epochs of training data vs the expert that that 700.</p>

<p><img src="/images/expert_novice.png" alt="'Expert vs Novice'" /></p>

<p>Another interesting visualization of the data is to look at the mean and standard deviation of the time series plotted on a graph where the x axis is the mean and the y axis is the standard deviation.  Here, each dot represents one time series or “mission”.</p>

<p><img src="/images/novice_expert_mean_std.png" alt="'Expert vs Novice'" /></p>

<p>Once the data has been prepared for all of the agents, an 80%/20% train/test split will be used to divide up the data.  While it would be possible to perform some type of cross validation on the data, the simple 80%/20% split will do for now.</p>

<h2 id="the-process">The process:</h2>

<p>For the proposes of comparison, the following classification techniques were considered:</p>

<ul>
  <li>IndividualBOSS</li>
  <li>KNeighborsTimeSeriesClassifier</li>
  <li>TimeSeriesForestClassifier</li>
  <li>MrSEQLClassifier</li>
  <li>MatrixProfileClassifier</li>
</ul>

<p>The following code is the main cell in the jupyter notebook that is responsible for training and testing the different models.  This code is also available in the URL mentioned at the end of this post.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>from sktime.classification.all import ColumnEnsembleClassifier, RandomIntervalSpectralEnsemble, RandomIntervalSpectralEnsemble, IndividualBOSS, KNeighborsTimeSeriesClassifier, ShapeletTransformClassifier, MrSEQLClassifier
import sktime.classification.all
from sktime.classification.feature_based import MatrixProfileClassifier
from datetime import datetime

classifiers = ['IndividualBOSS', 
            'KNeighborsTimeSeriesClassifier', 
            'TimeSeriesForestClassifier', 
            'MrSEQLClassifier',
            'MatrixProfileClassifier']

def factory(classname):
    try:
        cls = getattr(sktime.classification.all, classname)
    except:  #Unfortunate kluge for matrix profiles.
        cls = getattr(sktime.classification.feature_based, classname)
    return cls()

for c in classifiers:
    _ = factory(c)


print("Classifiers appear to be present.")

results = []
for classifier_name in classifiers:
    start = datetime.now()
    print("Working on: {}".format(classifier_name))
    start = datetime.now()
    classifier = factory(classifier_name)
    
    # Train the model
    classifier.fit(X_train, y_train)
    
    trained_t = datetime.now()-start
    
    start = datetime.now()
    
    # Predict results on test data
    y_pred = classifier.predict(X_test)
    
    inference_t = datetime.now()-start
    
    # Measure accuracy of predictions against "ground" truth.
    a = accuracy_score(y_test, y_pred)
    
    # Save resultes
    results.append([classifier_name, trained_t.seconds/len(X_train), inference_t.seconds/len(X_test), a])

df = pd.DataFrame(data=results)
df.columns = ['Classifier', 'Training_Time', 'Inference_Time', 'Accuracy']

print("Models trained.  Results in tabular form:\n")
print(df)    
</code></pre></div></div>

<h2 id="results">Results</h2>

<p>The following is the results of the testing process:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                    Classifier  Training_Time  Inference_Time  Accuracy
0                  IndividualBOSS          0.000            0.00     0.544
1  KNeighborsTimeSeriesClassifier          0.000            0.02     0.736
2      TimeSeriesForestClassifier          0.004            0.00     0.752
3                MrSEQLClassifier          0.069            0.00     0.580
4         MatrixProfileClassifier          0.003            0.00     0.448
</code></pre></div></div>

<p>If we limit the traning and testing to just the best and worst agents, the accuracies are actually much better:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                    Classifier  Training_Time  Inference_Time  Accuracy
0                  IndividualBOSS         0.0000             0.0      0.70
1  KNeighborsTimeSeriesClassifier         0.0000             0.0      0.84
2      TimeSeriesForestClassifier         0.0000             0.0      0.86
3                MrSEQLClassifier         0.0125             0.0      0.73
4         MatrixProfileClassifier         0.0025             0.0      0.69
</code></pre></div></div>

<h2 id="conclusion">Conclusion</h2>

<p>As can be seen from the above, the different time series classifiers in sktime offered different accuracies and different training and inference times.  The TimeSeriesForestClassifier appeard to provide the best results for this dataset.  Another interesting graph to consider in this experiment is the accuracy vs performance (training and inference time) for the different models.</p>

<p><img src="/images/performance_accuracy_time_series.png" alt="'Accuracy vs Performance'" /></p>

<p>This experiment only scrapes the surface of the tools available in the sktime toolbox.  I encourage you to check out sktime on your next time series project!</p>

<h2 id="references">References:</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>https://www.frontiersin.org/articles/10.3389/frai.2021.699448/full
https://www.sktime.org/en/stable/
</code></pre></div></div>

<h2 id="source-code">Source Code</h2>

<p>Source code is available at the url below. (Note the jupyter notebook for timeseries analysis is in the /game/examples/agents directory.):</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>https://github.com/fractalbass/lunar_lander_ml
</code></pre></div></div>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Reinforcement Learning meets Time Series Classification]]></summary></entry><entry><title type="html">A Perspective on Analytics, AI and Data Science</title><link href="/general/2022/02/12/data_science_35.html" rel="alternate" type="text/html" title="A Perspective on Analytics, AI and Data Science" /><published>2022-02-12T08:09:00+00:00</published><updated>2022-02-12T08:09:00+00:00</updated><id>/general/2022/02/12/data_science_35</id><content type="html" xml:base="/general/2022/02/12/data_science_35.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>When I started this blog, the first article I published was titled “What is data science?”  Now that I have some experience in the field, I thought it would be interesting to explore my current perspective on some commonly used, but frequently undefined terms.  The terms that I am choosing to focus on are the following:</p>

<ul>
  <li>Analytics</li>
  <li>AI (Artificial Intelligence)</li>
  <li>Machine learning</li>
  <li>Supervised, unsupervised and semi-supervised learning</li>
  <li>Deep learning</li>
  <li>Simulation</li>
  <li>Probability</li>
  <li>Statistics</li>
</ul>

<p>Since my first post, I have discovered that people have their own fairly unique perspectives and “mental map” of how the terms, techniques and disciplines above interrelate.  The following is the mental map that I currently use.  In many cases, the terms here overlap with each other.  There are some terms that are, perhaps, missing altogether such as Optimization.  I fully realize these facts.  I further realize that, as these fields mature and new fields emerge (such as quantum computing), my map will likely change to reflect the “state of the art and science.”</p>

<p>A single image is worth a thousand words.</p>

<h1 id="an-analytics-perspective">An Analytics Perspective</h1>

<p><img src="/images/analytics_perspective.png" alt="'An Analytics Perspective'" /></p>

<h2 id="comments-about-the-diagram">Comments about the diagram…</h2>

<p>As mentioned above, I choose to use the all encompassing term of “Analytics”.  My choice of this term is based on the fact that I have a Master of Science Degree from the Georgia Institute of Technology… in “Analytics”.</p>

<p>At the current time, I see Analytics consisting of Artificial Intelligence, Simulation, and Probability and Statistics.  I am considering replacing “Simulation” with the broader term “Operations Research.”  I think this substitution will allow me to more clearly place “Optimization” on the diagram.</p>

<p>I view Statistics and Probability as ways to describe the relationship between a population and samples of the population.  In probability, we often make statements about the likelihood of some event occurring based on some preconditions.  For example, what is the probability that I will pick a green marble out of a bag that contains 10 green marbles, and 10 red marbles?  In the reverse case, we might have, say 20 individual samples that we have drawn at random for a big bag of marbles.  From these samples, we may want to think about how many of a certain color of marbles there are in the overall population.  When we talk about going from populations to samples, we use probability.  When we make inferences about populations based on samples, we use statistics.</p>

<p>To me, the term Data Science is redundant.  The scientific method involves collecting data by conducting experiments in order to prove or disprove a hypothesis.  Based on this definition, it seems to me that for anything to be considered science, it is also data science.  You cannot take the data out of science without it becoming something else.</p>

<p>Wikipedia defines data science as:  “Data science is an interdisciplinary field that uses scientific methods, processes, algorithms and systems to extract knowledge and insights from noisy, structured and unstructured data,and apply knowledge and actionable insights from data across a broad range of application domains. Data science is related to data mining, machine learning and big data.”</p>

<p>Yeah, ok.  To me, the above just seems like an attempt to glorify the term “data science.”  That said, I am ok with someone saying “I am doing data science!”, if they are using data and following the scientific method.</p>

<p>The fact that I am being a bit negative about the term “data science” on a blog that is hosted at datascience.netlify.app isn’t lost on me.  In full disclosure, I should probably also mention that my current job title is “Lead Data Scientist”.  When I first started writing this blog, I was very excited about the term “Data Science”.  As I have gained more knowledge in this space, I have also come to realize how huge it is and how much there is that I don’t know.  I am tempted to say that, if I had it to do all over again, I may not use “datascience” in the name of my blog.  That, however, wouldn’t be truthful.  The term “data science”, for better or worse, seems to have stuck.  Call it marketing, I guess.  I plan on continuing to write about topics in Analytics on my blog:  “datascience.netlify.app”!</p>

<h2 id="disclaimer">Disclaimer</h2>

<p>Again, this “mental map” is based on my academic work and what I see in my career.  It likely will not fit with everyone else, and I am just fine with other definitions.</p>]]></content><author><name>Miles Porter</name></author><category term="general" /><summary type="html"><![CDATA[Introduction When I started this blog, the first article I published was titled “What is data science?” Now that I have some experience in the field, I thought it would be interesting to explore my current perspective on some commonly used, but frequently undefined terms. The terms that I am choosing to focus on are the following: Analytics AI (Artificial Intelligence) Machine learning Supervised, unsupervised and semi-supervised learning Deep learning Simulation Probability Statistics Since my first post, I have discovered that people have their own fairly unique perspectives and “mental map” of how the terms, techniques and disciplines above interrelate. The following is the mental map that I currently use. In many cases, the terms here overlap with each other. There are some terms that are, perhaps, missing altogether such as Optimization. I fully realize these facts. I further realize that, as these fields mature and new fields emerge (such as quantum computing), my map will likely change to reflect the “state of the art and science.” A single image is worth a thousand words. An Analytics Perspective Comments about the diagram… As mentioned above, I choose to use the all encompassing term of “Analytics”. My choice of this term is based on the fact that I have a Master of Science Degree from the Georgia Institute of Technology… in “Analytics”. At the current time, I see Analytics consisting of Artificial Intelligence, Simulation, and Probability and Statistics. I am considering replacing “Simulation” with the broader term “Operations Research.” I think this substitution will allow me to more clearly place “Optimization” on the diagram. I view Statistics and Probability as ways to describe the relationship between a population and samples of the population. In probability, we often make statements about the likelihood of some event occurring based on some preconditions. For example, what is the probability that I will pick a green marble out of a bag that contains 10 green marbles, and 10 red marbles? In the reverse case, we might have, say 20 individual samples that we have drawn at random for a big bag of marbles. From these samples, we may want to think about how many of a certain color of marbles there are in the overall population. When we talk about going from populations to samples, we use probability. When we make inferences about populations based on samples, we use statistics. To me, the term Data Science is redundant. The scientific method involves collecting data by conducting experiments in order to prove or disprove a hypothesis. Based on this definition, it seems to me that for anything to be considered science, it is also data science. You cannot take the data out of science without it becoming something else. Wikipedia defines data science as: “Data science is an interdisciplinary field that uses scientific methods, processes, algorithms and systems to extract knowledge and insights from noisy, structured and unstructured data,and apply knowledge and actionable insights from data across a broad range of application domains. Data science is related to data mining, machine learning and big data.” Yeah, ok. To me, the above just seems like an attempt to glorify the term “data science.” That said, I am ok with someone saying “I am doing data science!”, if they are using data and following the scientific method.]]></summary></entry></feed>